Introduction to the Pluggable Agentic AI Framework
The Pluggable Agentic AI Framework organizes multi-agent applications into seven layers, separating the work of retrieving data, selecting models, coordinating agents, enforcing security, serving users, observing behavior, and evaluating results. Its central proposition is that taking an agent into production requires an architecture for the whole system, beyond evidence that a model can complete a task.
In its reference architecture on Amazon Bedrock AgentCore, AWS describes each layer as having a distinct responsibility and a stable contract. The technologies in the reference implementation are examples rather than mandatory choices. Organizations can substitute components that fit their infrastructure and requirements while retaining the boundaries between layers.
That distinction matters when assessing what the framework offers. It is a blueprint for organizing production responsibilities, accompanied by a retail customer support implementation. It is not evidence that any application adopting seven layers will automatically meet its performance, security, or quality requirements. AWS explicitly says the hands-on implementation does not replace production security hardening, testing, and review.
The useful question for an engineering team is therefore how these boundaries help it control change. If model selection, tool permissions, and user-interface logic remain separable, teams have defined places to evaluate and modify them. The architecture’s value rests on maintaining those contracts, rather than simply assigning seven names to an existing application.
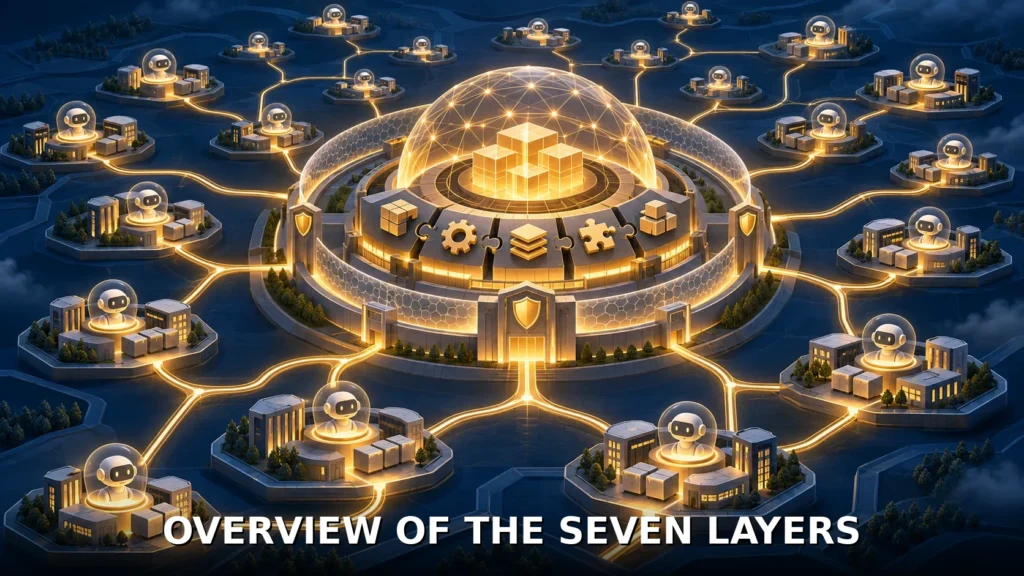
Overview of the seven layers
AWS’s seven layers cover both the path a request takes and the controls needed to operate that path. They should not be read as seven sequential model calls: security, observability, and evaluation address responsibilities that extend across the application.
| Layer | Responsibility in the reference architecture |
|---|---|
| Data and Knowledge | Retrieve relevant context from structured and unstructured data. |
| Model and Inference | Select and access models through configuration and a consistent interface. |
| Orchestration | Distribute work among agents and their permitted tools. |
| Security and Guardrails | Authenticate requests, authorize actions, protect data, and constrain behavior. |
| Application | Present the user experience and pass requests to orchestration. |
| Observability | Trace behavior and expose operational, usage, and cost signals. |
| Agentic Operations | Continuously evaluate quality and gate regressions. |
Data, inference, and orchestration
The Data and Knowledge layer accepts a query and returns relevant information as context for an agent. It owns retrieval, embeddings, and access to structured and unstructured information. AWS lists Amazon Bedrock Knowledge Base, Vector Engine for Amazon OpenSearch Serverless, Amazon S3 Vectors, and Amazon DynamoDB as example building blocks. The architectural responsibility is access to useful context; the particular storage or retrieval service is a separate choice.
Model and Inference keeps model choices in configuration instead of embedding them in application logic. AWS recommends evaluating models with realistic, representative business data, using smaller, faster models for simple tasks and larger models where more nuanced reasoning is needed. A routing layer with a consistent request-and-response contract separates agents from provider-specific APIs. The source identifies LiteLLM as an example of a common interface across providers.
Orchestration determines who performs the work. AWS recommends a single agent for straightforward tasks and a supervisor delegating to specialists for complex workflows spanning domains. Specialists have defined capabilities and scoped tools. A centralized registry catalogs agents’ tools, skills, and owners, while standardized protocols such as MCP (Model Context Protocol) and A2A (Agent to Agent) support discovery and invocation. The supervisor can discover specialists instead of being tightly coupled to them.
Application, controls, and operations
The Application layer contains the chat interface, API surface, or embedded widget. AWS recommends keeping it thin: present the conversation and pass requests to orchestration, with business logic kept out of the interface. It also describes a decision model at this boundary that returns probabilities indicating whether a request is in scope, needs a human, or is urgent. Application code applies thresholds to those scores so the full agent workflow runs only where it adds value.
Security and Guardrails supplies identity checks, permissions, data protection, and intervention mechanisms. Observability records what the system did and what it consumed. Agentic Operations adds continuous evaluation of whether the results remain grounded, accurate, and safe. Together, these responsibilities connect execution with accountability and quality control.
AWS illustrates the layers with a retail refund workflow. A supervisor delegates to an Order agent and a Refund agent. The Order agent retrieves delivery and purchase details from DynamoDB; the Refund agent retrieves tier-based policy rules from a knowledge base and calculates eligibility using delivery date, current date, and loyalty tier. Calls pass through AgentCore Gateway, with Policy in AgentCore enforcing access control before tool execution, and are traced through the observability layer. This is a concrete reference scenario, not a reported customer deployment or a performance benchmark.
Importance of security and guardrails
AWS places security in the initial design, identifying prompt injection, tool misuse, and memory and data poisoning among the risks. Its guidance starts with treating external content as untrusted and authenticating every request, whether initiated by a person, another agent, or an automated workflow.
Authentication establishes the caller’s identity. Fine-grained authorization then determines whether a particular tool call is allowed before execution. The distinction is essential to the proposed design: recognizing an agent does not, by itself, permit every action available somewhere in the system. AWS recommends temporary, scoped credentials rather than persistent secrets.
The same boundary appears in orchestration through bounded autonomy. A specialist should operate strictly within the tools it has been granted. AWS warns that accumulating tools, instructions, and context in one agent can increase latency, reduce accuracy, and enable actions beyond intended boundaries. Splitting responsibilities allows teams to test behavior, scale agents, and define security models independently. That separation supports security only when the tool permissions enforce it.
Data protection extends to both requests and responses. The source recommends masking sensitive information, including personal health information and personally identifiable information, so it does not appear in outputs or remain in memory. It also calls for tamper-evident audit trails of significant decisions, human approval gates for high-impact actions, and circuit breakers to halt anomalous behavior.
AWS names Amazon Bedrock Guardrails, Amazon Bedrock AgentCore Identity, and Policy in Amazon Bedrock AgentCore among the implementation options. These are components of its proposed defense in depth, rather than proof that the reference application has passed a particular security assessment. No such assessment is supplied. The practical implication is to review identity, tool authorization, data handling, and intervention separately instead of treating a guardrail service as the complete security design.
Challenges of proof-of-concept models
The gap AWS describes is between demonstrating a task and sustaining a service. A prototype may show that an agent can answer a request without establishing how it behaves under concurrent traffic, cost pressure, security review, or changing quality requirements. The source argues that teams often rebuild routing, guardrails, and observability independently and add them after the initial agent works.
This is an architectural criticism of prototype-led development, not a finding that a particular model is incapable of production use. The unresolved questions concern the system around the model: how requests are routed, what actions are permitted, how failures become visible, and how quality is checked after release. A successful demonstration supplies limited evidence about those responsibilities.
The framework makes those questions explicit. Model evaluation must use representative business data. Agent responsibilities and tool access must be bounded. Operational dashboards should exist before launch. Evaluation must continue beyond the release that first passed testing. In that sense, the seven layers provide a review structure for identifying what a demonstration has left untested.
The retail example helps explain the difference. Retrieving an order and applying refund rules exercises useful business logic, but production readiness also depends on the access checks and traces around those calls. AWS’s warning that the sample still requires hardening, testing, and review limits how teams should interpret its readiness.
The supplied source offers no load-test results, measured cost savings, or comparative reliability figures. It therefore supports the framework as a proposed approach to production design, while leaving its effectiveness for a particular workload to be established through implementation and evaluation. Claims about scaling should be read as architectural intent, not demonstrated capacity.
Flexibility in technology choices
Pluggability depends on stable contracts at layer boundaries. AWS identifies identity checks, access policies, and telemetry interfaces among those boundaries, alongside the request-and-response contract used for inference. Components can change while the rest of the application continues to interact through the agreed interface.
The source describes third-party integrations across several responsibilities: model and hosting providers in inference, search in orchestration, decision APIs in the application layer, guardrails in security, and tracing and monitoring in observability. Its stated aim is to let enterprises retain existing tools, fill gaps, and adopt capabilities incrementally instead of sourcing every decision from one vendor.
For model selection, the mechanism is particularly clear. A common interface allows evaluations to inform a change of model without rewriting application logic around a different provider API. Likewise, separating the supervisor from a registry of specialists makes discovery an explicit architectural function. These are specific forms of decoupling, rather than a general promise that every component can be exchanged without effort.
The important qualification is that a stable interface and equivalent behavior are different questions. As an architectural inference, preserving a contract can limit the scope of a change, but the replacement still needs evaluation against the application’s requirements. AWS’s own emphasis on realistic model evaluation and regression gates supports treating substitution as a controlled change, not as an exemption from testing.
The evidence does not provide a compatibility matrix, migration measurements, or comparative integration costs. Teams can use the framework to decide where substitutions should occur, but the source does not establish the effort involved for every alternative. Its strongest supported proposition is organizational and architectural flexibility: define responsibilities first, then select technologies to satisfy them.
The role of proactive monitoring
Observability in the framework begins before the first incident. AWS calls for logs and metrics alongside end-to-end agent traces, with dashboards for latency, error rates, and spend available before launch. Per-request signals include cost, token usage, time to first token, and whether a call is secure.
Traces matter because an agent workflow contains multiple decision points and tool interactions. In the retail reference scenario, tracing spans the supervisor, specialist work, and tool calls, providing a way to locate the step associated with an incorrect refund calculation. Aggregate metrics show patterns across requests; the trace provides the path through an individual workflow. AWS suggests Amazon CloudWatch with OpenTelemetry and Amazon CloudWatch Omni for tracing and metrics.
Agentic Operations addresses a related but distinct question: whether the application still performs its task correctly. AWS recommends scoring every production session for groundedness, accuracy, and safety, with a regression gate to catch quality drops before they reach customers. It identifies Amazon Bedrock AgentCore Evaluations for scoring and Amazon Bedrock AgentCore optimization for continuous performance tuning.
Read together, these layers separate operational visibility from judgments about answer quality. Latency and spend can describe how a workflow ran without establishing that its result was correct. Evaluation adds a quality assessment, while traces give teams context for investigating what happened. That connection is the framework’s useful operational principle.
AWS argues that proactive monitoring costs less than reactive firefighting, but the supplied evidence does not quantify that comparison. The actionable guidance is more specific: define telemetry and evaluation from the start, make costs and failures visible, and check behavior after changes. Whether the seven-layer design meets an organization’s needs will depend on those controls being implemented and tested, not on the architecture diagram alone.