Choosing the best AI agent frameworks for your project is less about finding a single winner and more about matching a framework’s trade-offs to the system you need to build. A framework owns the agent loop — calling the model, running tools, keeping state and deciding what happens next — and the seven leading options in late 2026 differ sharply in how much of that loop they control, how they orchestrate several agents, and where your code runs. Gartner predicts that by 2027, 40% of enterprise AI deployments will use multi-agent architectures, so the choice has a long tail. Versions and figures here are as of November 2026.
What an AI agent framework actually does
Every framework here handles the same five jobs: the loop (prompt the model, read the reply, decide whether to call a tool or stop); tools (a way for the model to act — search the web, query a database, call an API); memory (state across turns and runs); planning (breaking a goal into steps and recovering when one fails); and observability (a record of what the agent did, so you can inspect, test and price it). The labels predict lock-in: a library such as LangGraph gives you primitives and leaves the architecture to you; an SDK such as the OpenAI Agents SDK gives you ready-made parts; a platform such as LangGraph Platform or Vertex AI Agent Engine also hosts your agents.
How to choose: six decision criteria
Judge every framework below against the same six criteria. Control versus abstraction: do you define the flow yourself, or describe only roles and goals and let the framework run it? Language: Python-first teams have the widest choice. Multi-agent model: graphs, role-based crews, or conversation. Deployment: self-hosted, cloud-managed, or vendor-locked. Evaluation and guardrails: tracing, scoring and human approval built in, or bolted on. Maturity: maintenance cadence, documentation, community and licence.
Deployment, the fourth criterion, looks different for each option. LangGraph the library runs wherever your Python runs; LangGraph Platform adds managed hosting, from self-hosted to fully managed, with API endpoints and built-in persistence. Google ADK deploys to Cloud Run, Google Kubernetes Engine or Vertex AI Agent Engine, or anywhere Python runs — it is not tied to Google Cloud. CrewAI’s Agent Management Platform hosts crews, with a free tier of 50 workflow executions a month. The OpenAI Agents SDK is code you run yourself; there is no hosted service, and you pay the model provider. For AutoGen, Semantic Kernel and LlamaIndex, this research establishes no managed hosting option — they ship as libraries you host yourself, apart from LlamaIndex’s LlamaParse document platform, which is available as a remote service. Hosting details beyond those named here were not established by this research.
The leading frameworks at a glance: the best AI agent frameworks compared
Shortlist from this table, then read on for the reasoning.
| Framework | Languages | Orchestration | Licence | Best fit |
|---|---|---|---|---|
| LangGraph | Python, TypeScript | Graph / state machine | MIT | Long-running, stateful agents |
| CrewAI | Python | Role-based crews, sequential or hierarchical | MIT | Team-of-specialists workflows |
| AutoGen | Python | Conversational multi-agent | MIT | Conversation-driven teams; maintenance-only |
| Semantic Kernel | C#, Python, Java | Kernel plus plugins, agent groups | MIT | Enterprise Microsoft-stack integration |
| LlamaIndex | Python, TypeScript | Data-first agents and workflows | MIT | Retrieval-grounded agents over your documents |
| OpenAI Agents SDK | Python | Lightweight agent loop, handoffs | MIT | Small self-hosted agents on OpenAI models |
| Google ADK | Python, TypeScript, Go, Java, Kotlin | Hierarchical agents, workflow graphs | Apache 2.0 | Gemini and Google Cloud builds |
One warning: the Microsoft row moved. Microsoft Agent Framework reached 1.0 in April 2026 as the successor to both AutoGen and Semantic Kernel; AutoGen now receives only bug fixes and critical security patches, and Semantic Kernel remains active but is no longer the path for new agent work.
LangGraph and LangChain: maximum control, maximum surface
LangGraph is a low-level orchestration framework and runtime from LangChain for long-running, stateful agents. You model the agent as an explicit directed graph of nodes and edges with a typed shared state object; nodes read the state and return partial updates, edges decide which node runs next, and execution proceeds in super-steps. LangGraph reached 1.0 in October 2025 and, as of November 2026, sits at version 1.2.20 with roughly 44,700 GitHub stars.
Its defining feature is durable execution. Attach a checkpointer when you compile a graph and LangGraph snapshots the full state after every super-step; each run is keyed by a thread_id, so after a crash, a timeout or a pause, a fresh process reattaches to the same thread_id and resumes from the last completed super-step, recovering the checkpointed state. Durable backends are SQLite for a single server and Postgres or Redis for production; the in-memory saver is for development only. The same mechanism gives you human-in-the-loop: interrupt() saves a checkpoint and returns control, and the graph resumes from that exact point when the human responds. LangGraph does not prescribe prompts or an agent architecture, and LangChain itself is optional. The library is MIT licensed; the dev server behind the langgraph dev command is Elastic-2.0, which bars offering it as a managed service. The skeleton of a LangGraph program — state, graph and checkpointer, before any nodes are added:
from typing import TypedDict
from langgraph.graph import StateGraph, END
from langgraph.checkpoint.sqlite import SqliteSaver

class AgentState(TypedDict):
    messages: list

workflow = StateGraph(AgentState)
# Nodes and edges are added here: each node is a function
# that reads the state and returns a partial update.
checkpointer = SqliteSaver.from_conn_string("agent_checkpoints.db")
graph = workflow.compile(checkpointer=checkpointer)
Multi-agent frameworks: CrewAI and AutoGen
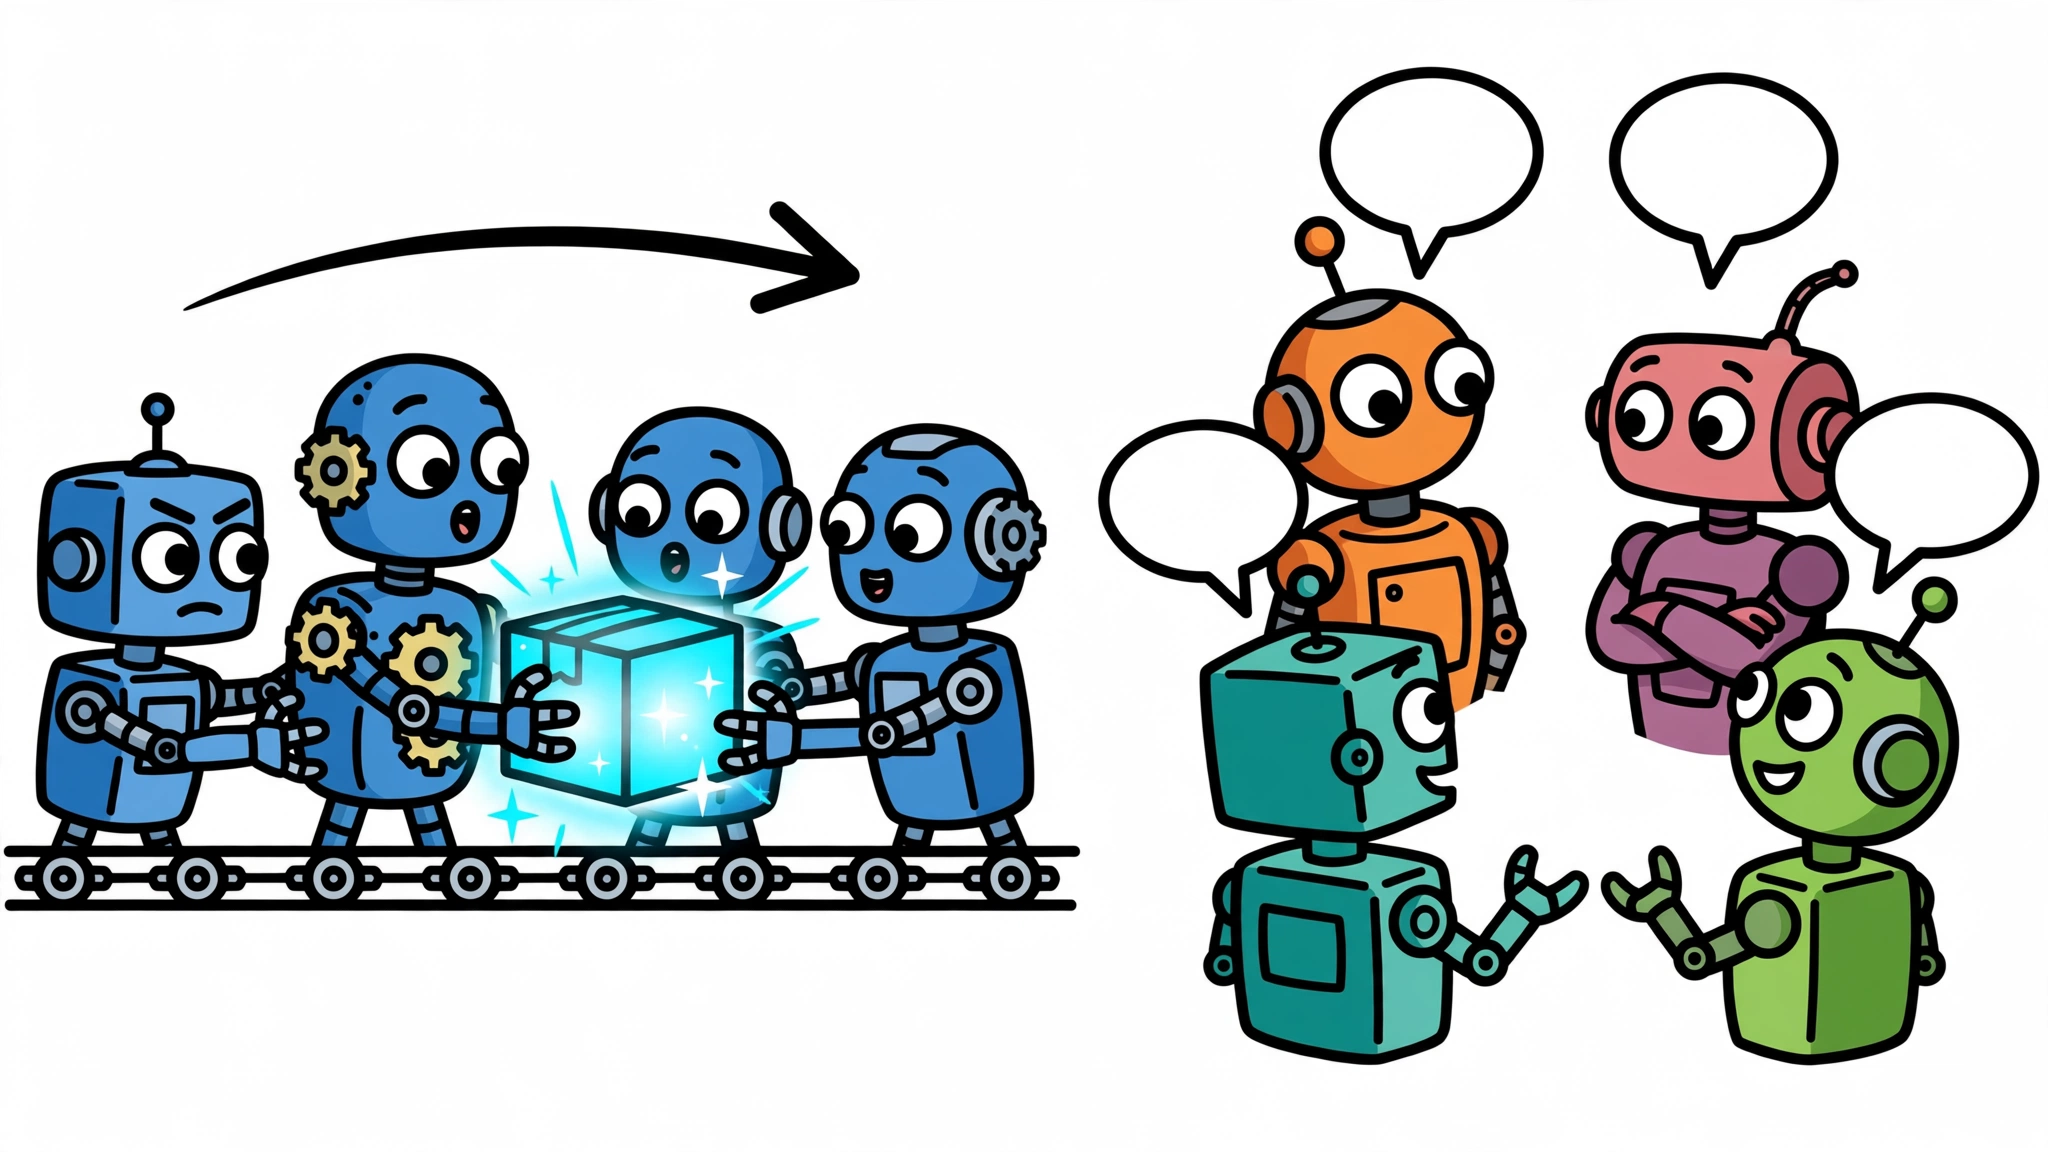
CrewAI and AutoGen both build teams of agents, but they organise the team differently. CrewAI is a Python framework built on three primitives that mirror how human teams work: an Agent has a role, a goal and a backstory; a Task has a description and an expected_output; a Crew is the container that runs the tasks and passes context between agents. Crews run sequentially or hierarchically, where a manager LLM assigns tasks, reviews outputs and re-delegates. CrewAI has built-in multi-tier memory, works with any LLM through LiteLLM, and adds Flows for event-driven orchestration. It is MIT licensed, at version 1.15.39 with roughly 60,700 GitHub stars. The shape of a minimal crew:
from crewai import Agent, Task, Crew, Process

researcher = Agent(
    role="Senior Market Researcher",
    goal="Discover and analyse cutting-edge AI developments",
    backstory="An experienced analyst who tracks new AI tools and frameworks.",
)

research_task = Task(
    description="Research the leading AI agent frameworks and summarise each one.",
    expected_output="A short summary of each framework with its strengths and limits.",
    agent=researcher,
)

crew = Crew(
    agents=[researcher],
    tasks=[research_task],
    process=Process.sequential,
)

result = crew.kickoff()
Set an OpenAI API key first; CrewAI defaults to OpenAI. AutoGen takes the opposite approach: agents collaborate through structured conversation. It is Microsoft Research’s open-source Python framework, introduced in a 2023 research paper, In the current AgentChat API, an AssistantAgent writes or reasons, a UserProxyAgent stands in for the human or executes code, and teams such as RoundRobinGroupChat and SelectorGroupChat decide who speaks next; tools are passed with a tools= parameter. Version 0.4 split the package into autogen-core, an asynchronous actor-model runtime, and autogen-agentchat, the high-level AgentChat API, and 1.0 reached general availability in February 2026. The older version 0.2 API used a GroupChat with a GroupChatManager and registered tools so one agent suggests the call and another executes it. AutoGen Studio provides a no-code web UI, and AutoGenBench is its evaluation harness. Choose CrewAI when the work maps naturally to human roles; choose AutoGen — or its successor, Microsoft Agent Framework — when the work is naturally a conversation. Whichever you pick, bound the run: decide in advance how long a conversation or crew may run and what counts as done. In CrewAI, tasks run in the order you list them, each task’s output feeding the next, or under a manager that assigns tasks and re-delegates as it reviews outputs — so keep that list fixed and each task’s expected output explicit.
Enterprise and cloud-native options: Semantic Kernel, OpenAI Agents SDK, Google ADK
Semantic Kernel is Microsoft’s open-source SDK for C#, Python and Java, described as lightweight middleware for enterprise-grade solutions, and it reached 1.0 across all three languages. Its core is the Kernel plus plugins: named containers of functions built from native code, prompt templates, OpenAPI specifications or the Model Context Protocol. An existing internal API can be added as a plugin with a few lines of code, and the same plugin is reusable across kernels and agents. Agents are built with ChatCompletionAgent, multi-agent collaboration uses AgentGroupChat, and the Process Framework models structured business processes. Filters provide enterprise control hooks, and built-in telemetry covers observability. Semantic Kernel is MIT licensed and remains active, but Microsoft Agent Framework is the successor for new agent work — treat Semantic Kernel as a proven incumbent rather than the forward default.
The OpenAI Agents SDK is a lightweight framework, and deliberately so. OpenAI describes it as enabling you to “build agentic AI apps in a lightweight, easy-to-use package with very few abstractions.” Its primitives are agents, tools, handoffs, guardrails, sessions and tracing; you give an Agent instructions and tools, pass it to Runner, and the Runner handles the loop until a final output. Released in March 2025, MIT licensed, it installs with pip install openai-agents and sits at version 0.24.0, below 1.0, so its interface is not yet declared stable. It uses the Responses API by default for OpenAI models and can connect to any provider following the OpenAI Chat Completions API format. Tracing is enabled by default and records what went into and out of each model and tool call — disable it by setting OPENAI_AGENTS_DISABLE_TRACING=1; it is unavailable under a Zero Data Retention policy. The shape of a first agent:
from agents import Agent, Runner

agent = Agent(
    name="Assistant",
    instructions="You are a helpful assistant.",
)

result = Runner.run(agent, "Hello")
Google ADK, the Agent Development Kit, is Google’s open-source, code-first framework for building, evaluating and deploying agents, released in April 2025 and at version 2.14.1 with roughly 20,500 GitHub stars. Its pieces are LlmAgent, an LLM-driven agent with instructions, tools and optional sub-agents; Workflow graph orchestration in the 2.x line, superseding the older SequentialAgent, ParallelAgent and LoopAgent agents; a Runner; a SessionService; and the adk command-line tool for scaffolding, running, a Dev UI, an API server, evaluation and deployment. Tools are plain Python functions — the docstring and type hints tell the model when to call them — plus built-ins such as Google Search and code execution, MCP servers and OpenAPI specifications. ADK is model-agnostic through LiteLLM and the Vertex AI Model Garden, speaks the Agent-to-Agent protocol natively, ships a built-in evaluation harness, and deploys to Cloud Run, Google Kubernetes Engine or Vertex AI Agent Engine. Apache 2.0 licensed, in Python, TypeScript, Go, Java and Kotlin, requiring Python 3.11 or newer. The command-line flow:
pip install google-adk
adk run my_agent
adk web
LlamaIndex belongs in this group as the data-first option. It is a Python and TypeScript framework that turns your documents into nodes, embeds them, stores them in a vector or graph index, and answers through a query engine — VectorStoreIndex is the simplest path. Agents are ReActAgent and FunctionAgent, and a query engine can be handed to an agent as a tool for retrieval-grounded answers. Workflows are directed graphs of steps, written as Python functions decorated with @step, for deterministic ordering, human-in-the-loop and parallel fan-out. LlamaParse handles document parsing, MCP servers expose the platform and documentation, evaluation includes a FaithfulnessEvaluator, and a CallbackManager emits events for observability tools such as Langfuse and Phoenix. It is MIT licensed. Pick LlamaIndex when the agent’s job is mostly answering over your own documents; pick the others when the job is mostly acting.
Matching a framework to your project
Three scenarios cover most real choices. A solo assistant: the OpenAI Agents SDK for a lightweight loop on OpenAI models, or LangGraph if it runs long jobs that must survive restarts. A team of specialists: CrewAI when the work maps to roles with clear handoffs, or AutoGen — or its successor, Microsoft Agent Framework — for a critique-and-revise conversation. An enterprise workflow: Semantic Kernel for existing .NET or Java systems, Google ADK for Google Cloud and Gemini, LlamaIndex for retrieval over internal documents. Finally, price the exit before you commit. Prompts, tools written as plain functions, and evaluation cases are the parts most likely to carry over; the orchestration itself — a LangGraph graph, a CrewAI crew and an AutoGen group chat are built on different models — and any state or checkpoint format are the parts most likely to need rework, so assess each part for reuse rather than assuming it moves.
Common mistakes and limits
Four failure modes recur across all seven frameworks, and no framework choice fixes them on its own. First, over-abstraction: a framework that hides the loop also hides the place where the loop goes wrong, so prefer one whose state you can inspect — LangGraph’s explicit graph, ADK’s event stream, CrewAI’s verbose task output — over one that only shows the final answer. Second, evaluation gaps: no framework ships a passing grade for your task. ADK has a built-in harness, LangChain’s LangSmith and AutoGenBench cover tracing and benchmarking, and LlamaIndex has a faithfulness evaluator, but you define the cases and the bar. Third, framework churn: AutoGen went from 0.2 to 0.4 to 1.0 to maintenance-only in about three years, ADK 2.0 introduced Workflow graph orchestration and deprecated the older SequentialAgent, ParallelAgent and LoopAgent workflow agents, which still work, and LangGraph’s prebuilt agent helper has been moving between import paths in the 1.x line. Pin your versions and read the migration notes before upgrading. Fourth, reaching for a framework when a plain loop would do: for a single short sequence of model and tool calls, consider calling the API directly instead of adopting a framework for one short task.
The best framework for developing AI agents is the one whose trade-offs match your project: LangGraph for durable, inspectable control; CrewAI for role-based teams; Microsoft Agent Framework for new Microsoft-stack work; Semantic Kernel for enterprise plugins; LlamaIndex for document-grounded agents; the OpenAI Agents SDK for a lightweight loop; Google ADK for Gemini and Google Cloud. Pick on the six criteria and re-check the versions.