What Is an AI Agent and How Does It Work?
Introduction: Beyond Chatbots to Autonomous Systems
An AI agent is a software system that pursues a goal by making decisions and taking actions on a user’s behalf. Its operating pattern is a feedback loop: read the current state, plan a step, execute an action, observe the result, update the state, and repeat until the goal is achieved or time runs out.
That loop is the starting point for understanding autonomy. The system can decide how to advance a task across multiple steps, using results from earlier actions to inform later decisions. For builders, the next question is how to control that process. Orchestration, tools, memory, and guardrails provide a practical architecture for doing so. Andrii Furmanets’ architecture guide describes the loop; Neoteric’s architecture guide organizes the implementation around those four layers.
What Is an AI Agent? Core Definition and Distinguishing Characteristics
Google Cloud defines AI agents as systems that use AI to pursue goals and complete tasks, combining reasoning, planning, memory, and autonomy. Here, autonomy means the ability to make decisions about task execution without requiring the user to choose every next step. Permissions and approval requirements still determine what the system is allowed to do.
A useful functional breakdown is perception, planning, memory, and action. Perception gathers information about the environment. Planning selects steps toward the goal. Memory stores and recalls information. Action executes decisions. These describe the agent’s behavior; the four engineering layers below explain how to organize and constrain that behavior.
For a system built around a large language model, the distinction to look for is the surrounding process: does it maintain task state, execute actions, and use observed results to choose subsequent steps? A model’s reasoning capability is only one part of that system. Google Cloud identifies ReAct, or Reasoning and Acting, as a pattern combining reasoning with action and external input.
How AI Agents Work: The Core Control Loop
The control loop connects decisions to their consequences. In Furmanets’ description, state includes the conversation, task, environment, and memory.
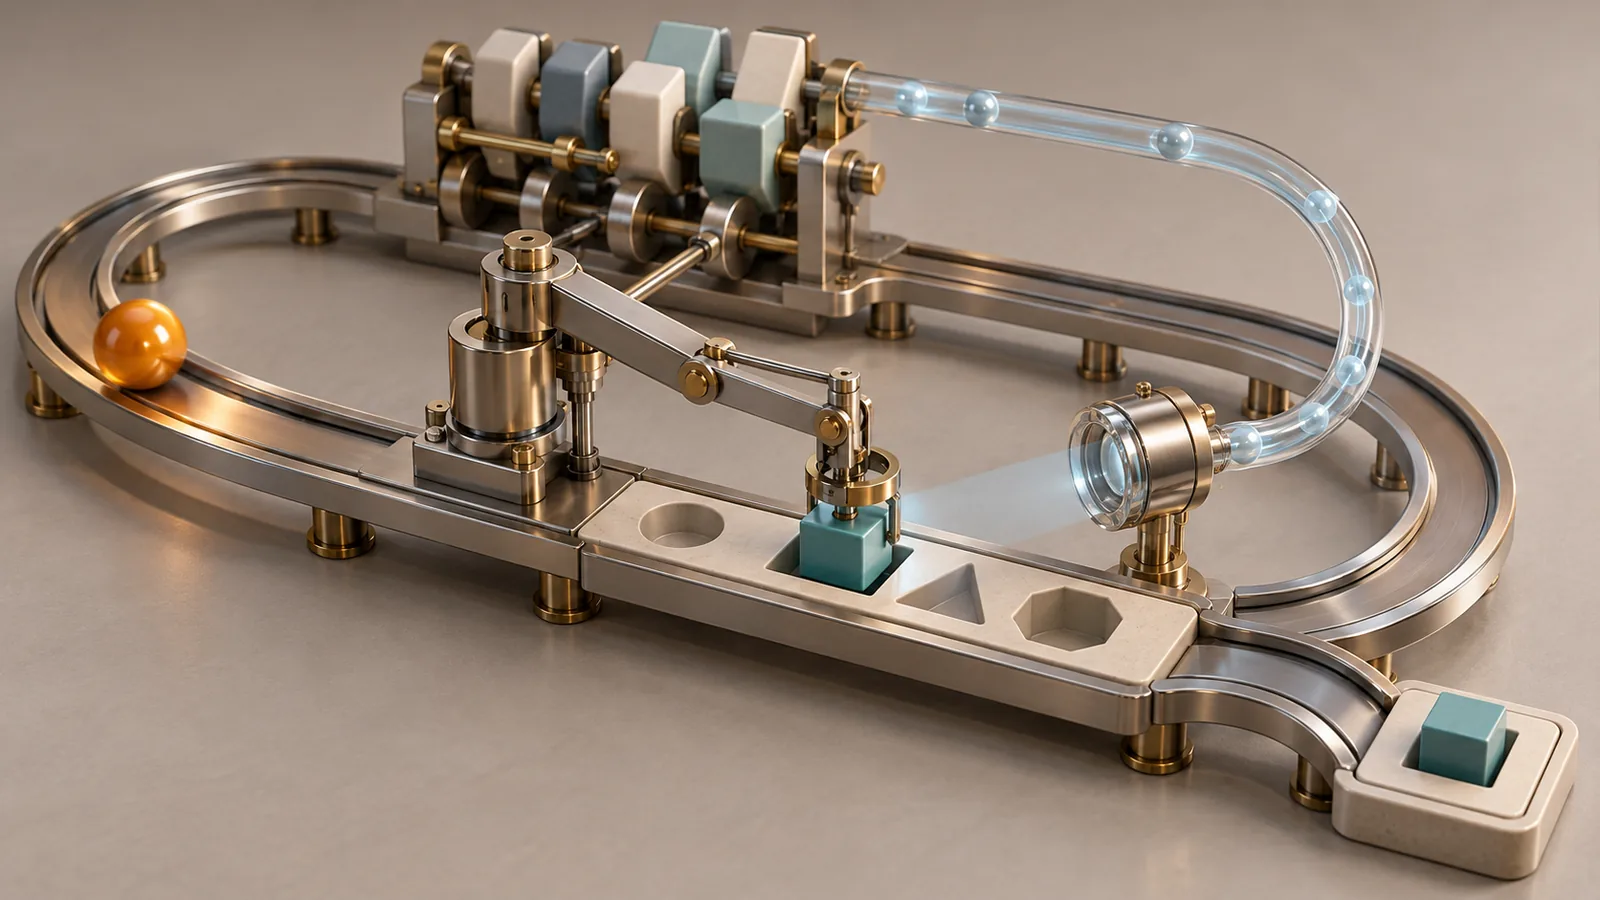
Control-loop diagram: Read state → Plan next step → Execute tool or action → Observe result → Update state → Return to read state. Exit when the goal is achieved or a timeout occurs.
Diagram description: Each action produces an observed result that updates the state used for the next planning step. The cycle continues until completion or timeout.
The following is conceptual pseudocode expressing that sequence, not executable code or a verified implementation:
Repeat until the goal is achieved or a timeout occurs:
    Read the current conversation, task, environment, and memory
    Plan the next step
    Execute the selected tool or action
    Observe the result
    Update the state
The important transition is from an action’s result to the next decision. Planning cannot simply assume that execution succeeded. A failed tool call is information the system needs to incorporate before continuing.
Illustrative AI research agent workflow. A research agent could search the web through a search API, evaluate the returned material, store findings, and synthesize a report. After each search, the results become part of the state used to choose the next step: search → evaluate → store → summarize. Fact-checking rules and citation requirements would constrain what enters the report. This illustrates the control loop rather than documenting a deployed system.
Repeatable control flow also should not be confused with identical decisions on every run. The loop specifies the sequence of operations; it does not establish that every plan or outcome will be the same. The implementation questions are concrete: what state is carried forward, what counts as completion, and when must execution stop?
The Four Layers of AI Agent Architecture
Neoteric recommends discussing architecture before development, using four practical layers: orchestration, tools, memory, and guardrails. Each controls a different part of the run. Their value is easiest to assess through the decisions they require.
Orchestration: Coordinating Work and State Management
Orchestration is the coordination layer that turns an objective into executable steps and manages their order and context. JetBrains’ explanation includes sequencing, communication between agents, retries, and workflow control.
For a single agent, this means coordinating its steps and ensuring the next step receives the relevant context. When several agents participate, communication becomes another responsibility. Adding agents does not remove the need to decide how work progresses or how failures are handled.
Illustrative customer support workflow. For a refund request, a support agent could query a customer relationship management (CRM) system, check the refund policy, prepare a recommendation, route it to a human for approval, and execute the refund only after approval. Orchestration would carry the request and policy result between steps and pause execution at the approval gate.
The production decision is who controls continuation: which result allows the workflow to advance, which failure triggers a retry, and which condition ends the run? As a design risk, weak sequencing can allow later steps to proceed on incomplete context. Unbounded retries can consume resources without completing the task. These are reasons to make workflow control explicit, rather than evidence of a particular system’s failure rate.
Tools: Connecting Agents to Business Systems
Tools provide the connections through which an agent acts on business systems. Furmanets describes them as APIs with strict contracts: typed and validated inputs, structured outputs, idempotent operations, and defined timeout, retry, and cost budgets.
Typing specifies what kind of input a tool accepts; validation checks whether an input meets the contract. Structured output gives the surrounding system an agreed form for interpreting the result. Together, they make the boundary between a proposed action and an executed operation easier to inspect. The tool-contract guidance treats these requirements as part of the architecture.
Idempotency means repeating the same operation does not create an additional effect. That matters when a system retries an action. The design question is whether repeating the call is safe, alongside how many attempts are allowed and how long they may take.
A connection to an API is therefore only the beginning. Before giving an agent access, establish the accepted inputs, returned results, failure handling, and operating budget. If those contracts are unclear, the workflow has no reliable basis for deciding whether to retry or continue.
Memory: Layered Information Storage and Recall
Memory carries information between decisions. Furmanets recommends separating it into layers:
| Memory layer | Role |
|---|---|
| Working memory | Immediate context needed for the current task |
| Summaries | Intermediate information retained in condensed form |
| Artifacts | Persistent data produced or retained during work |
| Long-term preferences | Historical information that can inform later behavior |
This division turns a broad requirement to “remember” into specific retention decisions. Immediate task context and information intended for future work serve different purposes. Teams need to decide what each layer receives and what is recalled into the next planning step. The layered-memory pattern supplies the organizing principle, rather than a required storage product.
The practical risk is losing relevant information between steps or carrying forward information that no longer belongs in the current context. Memory design should therefore be reviewed together with orchestration: storing a result helps only if the workflow supplies it where it is needed.
In the research example, the current question and search results could sit in working memory, condensed findings in summaries, and stored findings and the report in persistent artifacts. A database storage tool could retain those findings beyond the current step. The next planning step would need the relevant findings in context; storing them alone would not complete the loop.
Guardrails: Permissions, Policies, and Safety Boundaries
Guardrails define permissions, approvals, and safety policies. In Neoteric’s four-layer model, these are architectural decisions made before development, alongside the agent’s tools and memory.
The central questions are what the agent may do independently, what requires approval, and what policy limits apply. A tool being available does not settle whether the agent should be authorized to use it in every circumstance.
In the refund example, the approval requirement would be a guardrail: access to the refund API would not itself authorize execution. The workflow would need to enforce the human approval gate before performing the refund.
Monitoring has a related role. Hugging Face’s observability course describes detecting harmful language and prompt injection as observability concerns. Detection should be considered alongside permission boundaries; it is not evidence that every harmful action will be prevented.
Architecture decision checklist
Before building, or evaluating a platform, make these decisions explicit:
- Orchestration: What determines the next step, how is context passed, and how are retries and termination controlled?
- Tools: Which business systems are accessible, what are their input and output contracts, and what timeout, retry, and cost budgets apply?
- Memory: What belongs in working context, summaries, persistent artifacts, and long-term preferences?
- Guardrails: Which permissions, approvals, and safety policies constrain execution?
Use the same checklist for a custom implementation and a platform offering. It frames the responsibilities to evaluate without assuming that either approach supplies them automatically.
AI Agents vs. AI Assistants vs. Bots: Key Differences
Google Cloud distinguishes agents from assistants by independent decision-making and proactive execution of complex, multi-step tasks. Assistants respond to user requests and offer recommendations while leaving decisions to the user.
| Dimension | AI agent | AI assistant | A system labeled “bot” |
|---|---|---|---|
| Purpose | Pursue goals and complete tasks on behalf of a user | Respond to requests and provide assistance or recommendations | The label alone does not establish its purpose |
| Capabilities | Reasoning, planning, memory, and action across multiple steps | Request-driven assistance | Examine the actual workflow |
| Autonomy | Independently chooses how to advance a task | Leaves decision-making to the user | Check who selects the next step |
| Decision authority | Makes execution decisions within permissions and policies | User retains decision-making | Check its permissions and approval boundaries |
| Interaction model | Can proactively perform multi-step work | Responds to user requests | Check whether it acts and incorporates results |
The agent and assistant columns reflect the supplied distinction. The bot column is a classification checklist, not a claim that every bot has the same architecture. For scoping a project, inspect the system’s behavior and authority rather than relying on its product label.
Observability: Making Agents Transparent and Trustworthy
Observability means understanding execution through logs, metrics, and traces. Hugging Face’s course describes tracking actions, tool usage, model calls, and responses to support debugging and performance improvement.
A trace represents a complete task or agent run. A span represents an individual step within it. That distinction helps operators connect an overall result with the sequence that produced it.
For the illustrative refund workflow, a trace could connect the CRM query, policy check, recommendation, approval, and refund execution, with spans recording the individual steps. Cost tracking across that run would help operators assess the workflow as a whole.
A production dashboard can organize the course’s monitoring dimensions as follows:
| Dimension | What to track | Operational question |
|---|---|---|
| Latency | Response time for the run and its steps | Where is execution taking time? |
| Cost | Expense per agent run | How does resource use relate to the outcome? |
| Request errors | Failed API or tool calls within the trace | Which operations fail, and what follows the failure? |
| Explicit feedback | User ratings and comments | What problems do users report? |
| Implicit feedback | Behavior such as query rephrasing | Which interactions may need closer review? |
Read these measures together. A fast response is not sufficient evidence of task success, and rephrasing is a signal to investigate rather than a complete explanation of what went wrong. Traces provide the execution context needed to interpret aggregate metrics.
Evaluating Agent Performance: Beyond Text Quality
Observability records what happened; evaluation asks whether the run achieved the right result. IBM’s agent-evaluation guidance covers multi-step reasoning, tool calling, interaction with external systems, task success, alignment with user intent, and cost efficiency. It also includes safety, trustworthiness, and policy compliance.
An evaluation should therefore answer several separate questions. Did the agent complete the intended task? Were its tool calls and interactions appropriate? Did it remain within policy? What did completion cost? A readable final response cannot answer all of them.
Illustrative coding agent with a testing loop. A coding agent could interpret requirements, write code, run tests through a test runner API, inspect failures, revise the code, and repeat before finalizing. Test results would provide an objective check for the behavior those tests cover; failed results would remain in task state to guide the next revision. Passing tests would not by itself establish complete task success or policy compliance. An iteration limit and cost budget would bound the loop.
Define those criteria alongside the workflow. The observable steps then provide evidence for assessing execution, while the final outcome is assessed against the user’s goal. Avoid collapsing all of these dimensions into a judgment about writing quality.
Real-World Challenges: What Production Reveals
The architecture points to several failure paths worth examining. These are design implications of the control loop and its safeguards, not measured failure rates or claims about a particular deployment.
Errors can carry forward. If an unsupported conclusion is retained as reliable state, later planning may build on it. This is the cascading-hallucination risk: a feedback loop can propagate a mistaken premise as well as a useful result. State handling and evaluation deserve attention at intermediate steps.
Repetition needs a boundary. A loop needs completion and timeout conditions. Retries also need budgets. Without an effective stopping condition, repeating the sequence does not establish progress and may continue indefinitely.
Cost is a property of the run. Multiple actions and retries must be assessed together through expense per run. Monitoring response time and spending alongside task success makes the trade-off visible; no universal acceptable budget follows from the architecture alone.
Visibility and permission solve different problems. A trace can show that an action occurred. Permission and approval rules determine whether it was allowed. Production review needs both the execution record and the boundaries against which to assess it.
Conclusion: From Demo to Reliable Production Agents
A useful build-or-buy review should ask for more than a successful demonstration: inspect the workflow controls, tool contracts, memory decisions, permission boundaries, execution traces, and task-level evaluation criteria. These make the proposed system concrete enough to assess.
The evidence does not establish a universally best platform, model, or deployment threshold. It supports a more practical decision: determine whether the system’s authority and operating controls fit the task before treating a working run as proof of readiness.
Explore more AI Agents coverage.