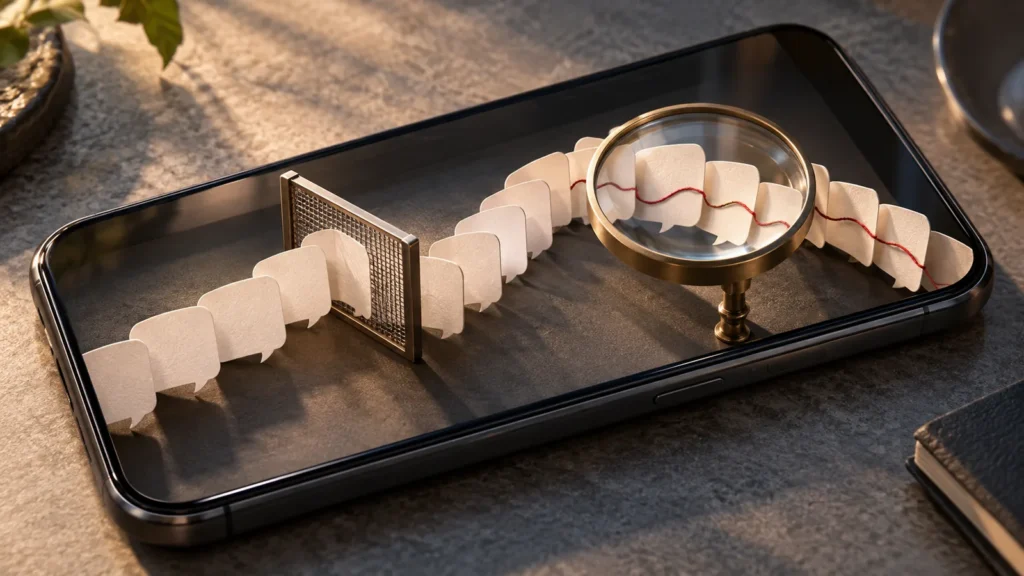

Google DeepMind and Singapore’s Government Technology Agency (GovTech) have announced an on-device scam detection model that combines a lightweight message classifier with a fine-tuned Gemma model. The first stage screens incoming messages; the second examines a larger conversation snapshot to assess possible manipulation. Google says the system analyses conversations locally and warns users before they share sensitive information or money. Google DeepMind’s announcement
Presented at Singapore International Cyber Week 2026, the collaboration sits within Google’s National AI Partnership with the Singapore Government. Its central technical proposition is to bring context-sensitive scam detection onto smartphones while preserving private conversations. The announcement describes the architecture and training safeguards, but it does not establish measured detection accuracy or a completed consumer rollout.
Why conversation context matters
Google DeepMind frames the problem as a shift from simple phishing toward social engineering: attackers use convincing conversations to manipulate victims before requesting money. According to its announcement, scams account for more than half of Singapore’s reported crimes and more than S$4 billion in losses since 2019. It says social engineering scams now account for up to 80% of losses. These figures describe the problem the developers are targeting; they are not measures of the model’s effectiveness.
The team fine-tuned a lightweight Gemma model on local scam conversations, including impersonations of public institutions, banks and local figures, alongside trending regional schemes. Google says generic models can struggle with local deception techniques and presents this adaptation as a way to distinguish benign conversation from manipulation.
The architectural implication is that an individual message serves as an initial signal, while a wider exchange informs the subsequent assessment. That fits the stated threat: persuasion unfolding through a conversation. Local fine-tuning supplies examples of the targeted scam narratives; the second stage supplies more conversational context. Neither design choice, by itself, proves how reliably the system separates a scam from an innocent exchange.
How the two-stage pipeline works
Battery efficiency is a central constraint in Google’s account of the system. Rather than describing a single model performing every assessment, the announcement divides detection into two stages with different responsibilities.
| Stage | Documented operation | Intended role |
|---|---|---|
| 1: Initial screening | A lightweight, efficient classifier screens inbound messages using minimal power. | Identify potential threats. |
| 2: Contextual evaluation | The fine-tuned Gemma model analyses a larger snapshot of the conversation. | Confirm a threat or discard a false alarm. |
This division places an inexpensive screening step before the contextual assessment. It is a design response to the tension between ongoing message screening and the cost of running a more complex model on a phone. Google describes the model as optimised for typical smartphones in Singapore, but the available announcement details do not quantify power consumption or identify minimum hardware requirements.
When the model detects manipulative conversational patterns, it triggers a real-time warning on the user’s device, advising the person to pause before sharing information or funds. The described intervention is therefore a warning that supports a user’s decision. The evidence does not establish automatic blocking of messages or payments.
For developers assessing this architecture, the boundary between the stages deserves attention. The contextual model is intended to reject false alarms, but that does not establish how many it rejects or how often initial screening misses a threat. The announcement supplies no numerical false-positive rate, missed-threat rate, detection latency or battery benchmark. The two-stage design explains the intended efficiency mechanism; its operating trade-offs remain unquantified in the supplied evidence.
Local analysis and encrypted messaging
Google’s privacy argument concerns where conversation analysis happens. Its announcement contrasts on-device processing with server-side message scanning and notes that end-to-end encrypted messaging platforms cannot inspect private conversations on their servers. Bringing analysis onto the device is intended to allow protective assessment without sending those conversations to a cloud service.
Channel NewsAsia reports that the model will analyse conversational patterns locally without sending data to external servers. The distinction matters: local conversation processing describes operation of the detector, while the project’s cloud environment was used for fine-tuning. A cloud-based training environment and on-device detection address different parts of the system’s lifecycle.
Google says messaging platforms and operating system vendors can directly integrate these lightweight models. That makes integration part of the practical deployment question. The announcement describes a model for protecting encrypted conversations, but the supplied evidence does not identify a messaging service where this particular model is already enabled or document the interface through which it accesses conversation context.
How training data was governed
The announcement identifies three development safeguards. Under its Sovereign Sandbox arrangement, fine-tuning took place within GovTech’s managed and maintained GCP environment, keeping training data isolated. Google says training excluded private or personally identifiable information and used anonymised datasets derived from scam reports and intelligence feeds. It also says the model was tested against synthetic dialogues and local corpora covering diverse scam categories and evolving impersonation tactics.
These safeguards address distinct questions: control of the fine-tuning environment, the information included in training, and the scenarios used for testing. They should not be treated as interchangeable evidence of privacy or accuracy. Training-data exclusion is separate from the commitment to analyse users’ conversations locally, and a description of stress-testing is separate from published test results.
The local datasets and regional scam narratives make the project specifically grounded in Singapore’s threat environment. The supplied evidence does not establish equivalent performance in other countries or languages. Any broader assessment would need evidence beyond the model’s stated local adaptation.
An announced model, with installation details still pending
The reporting uses different descriptions of the project’s maturity. Google DeepMind says the collaboration has delivered an on-device model; Channel NewsAsia describes GovTech and Google DeepMind as developing real-time detection. These accounts support the existence of the announced collaboration and model, while leaving consumer availability less clear.
According to Google, as reported by Channel NewsAsia, the model is intended for Android devices, and further details on installation and use will be announced soon. Readers should therefore distinguish the technical announcement from instructions to install a finished service.
For technical decision-makers, the contribution is a concrete architecture: local scam-specific fine-tuning, a lightweight screening stage, a contextual Gemma assessment and a warning delivered on the device. The remaining questions concern measured effectiveness and deployment—how accurately the stages work together, what resources they require, and how users will receive the protection. Those answers will determine how the stated privacy and efficiency goals translate into an operational service.