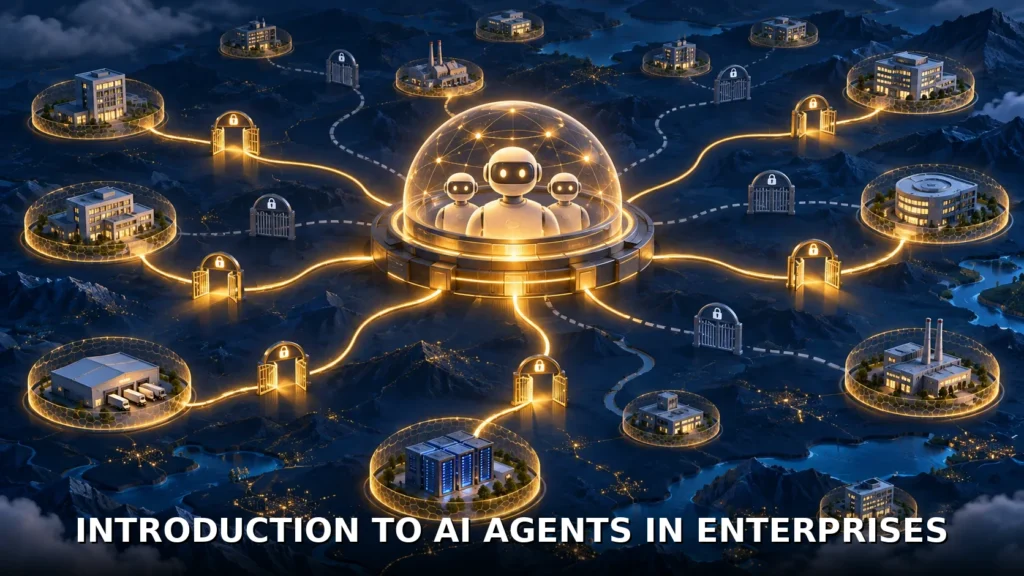
Introduction to AI agents in enterprises
An AI agent that searches company documents needs a reliable way to establish whose permissions govern every search. If the language model can choose that identity, a shared assistant can retrieve information for the wrong employee or customer. Fine-grained access control therefore depends on connecting verified user identity to retrieval permissions throughout the request path.
AWS describes an architecture for Amazon Bedrock Managed Knowledge Base tools that makes this separation explicit. Trusted code derives the user’s identity from a validated token, a gateway inserts that identity into tool calls, and the knowledge base filters documents using their access controls. Additional policies check the identity assignment and restrict which infrastructure can search the knowledge base.
AWS frames the problem around growing enterprise use of agents that search internal documents to compose answers. Its fictional AnyCompany example uses one assistant and one knowledge base for employees in two departments. Each department has a business plan, while a notice is shared across both. An employee asks the assistant to compare their department’s plan with the shared notice and identify delayed initiatives.
The assistant generates search queries and continues retrieving information until it has enough material. Without user-specific restrictions, the other department’s business plan could enter the answer. The same access problem applies when the shared assistant serves different customer companies in a multi-tenant software service.
This is a worked architecture, rather than evidence that every agent deployment has the same exposure. Its value is the clear boundary it draws: the agent chooses what to search for, while trusted application infrastructure establishes who is searching. The sample agent forwards the signed-in user’s access token to the gateway and contains no access-control logic of its own.
Importance of fine-grained access control in AI systems
The central security requirement is that information used to compose an answer stays within the requesting user’s permissions. A relevant document can still be unauthorized. Search relevance and permission to retrieve are separate questions, and the architecture needs to answer both before document chunks reach the agent.
In AWS’s design, Amazon Bedrock Managed Knowledge Base supplies the retrieval backend. Amazon Bedrock AgentCore Gateway exposes that backend as Model Context Protocol (MCP) tools. ACL awareness, the knowledge base’s access control list feature, filters retrieved documents using the user context supplied with a search request.
That filtering has a critical qualification: Managed Knowledge Base does not authenticate end users. It trusts the supplied userContext. As AWS explains, ACL awareness is not an authorization mechanism by itself. If the wrong identity reaches retrieval, filtering can operate as designed while selecting documents for the wrong person.
The architecture addresses this dependency through controls at two layers:
| Layer | Primary control | Additional defense |
|---|---|---|
| AgentCore Gateway | A request interceptor overwrites userContext using the verified token | Policy in AgentCore checks that userContext.userId matches the token’s email claim |
| Managed Knowledge Base | ACL awareness restricts returned documents to those available to the supplied user | A resource-based policy denies searches from principals other than the gateway execution role |
These controls have different responsibilities. The interceptor binds a search to the authenticated user. ACL awareness applies document permissions for that user. The policy check guards against a mismatch if identity injection fails, while the resource-based policy addresses searches that bypass the gateway.
AWS states that the two primary defenses are sufficient for requests through the gateway, provided no other principal can call the knowledge base. It recommends the resource-based policy if other principals in the account have bedrock:Retrieve permissions. That condition matters: a correctly configured gateway does not establish a complete boundary if another permitted caller can reach retrieval with a different user context.
The broader design lesson is that access control is a property of the whole request path. Authenticating a user, assigning an identity to a tool call, filtering results, and restricting alternate callers each answer a different part of the access question.
Challenges of multi-tenant data access
The distinctive challenge in the documented agent workflow is who constructs tool arguments. In a traditional application, application code identifies the signed-in user and searches with that user’s permissions. In the agent workflow described by AWS, the language model selects a tool and supplies arguments at runtime. Exposing an identity field as an ordinary argument gives the model influence over the retrieval scope.
The Managed Knowledge Base connector illustrates how this happens. Its default tool schema lets the model supply only the search query, with the administrator fixing the target knowledge base through parameterValues. To enable ACL-aware searches, the connector must also expose userContext through parameterOverrides.
The resulting MCP tools are named <target-name>___Retrieve and <target-name>___AgenticRetrieveStream. The first performs hybrid search. The second breaks a query into subqueries and iteratively searches multiple knowledge bases. Both need the same trustworthy identity context when used for user-specific access.
Exposing userContext creates a problem because a model can set any value for an exposed argument. AWS gives the example of one user asking the assistant to search as another. An LLM error or an indirect prompt injection in a retrieved external document can also produce an incorrect identity. These are documented failure scenarios, not measurements of how often such events occur.
Neither the gateway nor the knowledge base independently verifies that the supplied userContext belongs to the authenticated user in the unprotected connector flow. The gateway also does not populate that field from the caller’s IAM identity. The caller’s infrastructure identity and the end user’s document-access identity therefore require an explicit connection.
This distinction becomes especially consequential in the shared-customer setting described by AWS. The same assistant and knowledge base can serve multiple customers, so choosing the wrong end-user identity can cross a customer boundary. The source’s departmental example demonstrates the access pattern; it does not provide an independently measured assessment of a production multi-tenant deployment.
An implementation detail makes the solution less obvious: the connector target has no custom tool code, and only fields exposed through parameterOverrides can be passed as tool arguments. Consequently, userContext must remain exposed even though clients do not need to set it. The protection comes from trusted interception and enforcement after the request arrives.
Design principles for user identity verification
The governing principle is to keep the language model out of identity determination. AWS’s sample uses an identity provider, token validation, deterministic request modification, and a separate policy check to connect a signed-in person to a search.
The user first signs in with Amazon Cognito and receives an access token in JSON Web Token (JWT) form. A pre token generation Lambda trigger adds an email claim, but only when the email is verified. The agent forwards the access token in the Authorization header of its MCP requests to AgentCore Gateway.
The gateway’s JWT authorizer validates the token’s signature, expiration, and client ID. A Lambda request interceptor then obtains the email from that validated token and overwrites arguments.userContext on tools/call requests. The assigned userId is the authenticated user’s email, regardless of the value supplied by the client or model.
The overwrite is the important behavior. Merely supplying an identity when the argument is absent would leave an existing client-supplied value in control. In the documented implementation, each tool call receives the token-derived identity even when the incoming request already contains a different one.
The interceptor also rejects request bodies that are not a single JSON-RPC object, including batches. It rejects tool calls when the token has no email claim or the tool arguments are invalid. These checks make the documented failure behavior explicit: the request does not proceed with an unverified substitute identity.
Token decoding inside the interceptor relies on prior validation by the gateway’s JWT authorizer. The source code comments distinguish these responsibilities: the authorizer has already verified the signature and expiration, so the interceptor decodes the token to resolve the email. Preserving that order is part of preserving the design’s trust assumptions.
There is also a concrete deployment prerequisite. Cognito access tokens do not contain an email claim by default. The sample uses a pre token generation trigger with event version V2_0, whose access token customization requires the Essentials or Plus feature plan. AWS says that a Lite plan user pool leaves the token without the required email claim, causing the interceptor and Policy in AgentCore to deny every tool call.
After interception, Policy in AgentCore evaluates the modified request against a Cedar policy. According to the architecture description, it denies requests when userContext.userId differs from the JWT email claim. This is a second check on the identity binding, intended to cover an interceptor bug or bypass.
The provided evidence describes that policy’s intended behavior but ends before its detailed implementation. It supports explaining the control’s role, not reproducing a complete Cedar policy. Likewise, the architecture describes a resource-based restriction on the knowledge base without supplying its complete policy definition in the available text.
Role of ACL awareness in document retrieval
Verified identity becomes useful only when retrieval applies the corresponding document permissions. Managed Knowledge Base retains data-source access permissions at ingestion and uses them to filter searches. Requests supply the user’s email in the top-level userContext.userId field for both Retrieve and AgenticRetrieveStream.
For an Amazon S3 data source, AWS describes two ways to supply ACLs: a global ACL file for an S3 prefix, or a metadata file for each document. The sample uses per-document metadata. Its department A business plan grants access to user-a@example.com, with the ACL entry specifying Name, Type, and Access; the respective values are the user’s email, USER, and ALLOW.
Several ingestion behaviors affect how this works in practice. A document without an ACL entry is not ingested into an ACL-enabled S3 data source. Changing a global ACL file requires reindexing the affected prefix. Per-document metadata takes precedence over the global file, and changes to it reindex only the affected documents.
Permission freshness also has a defined limit. Amazon S3 has no real-time ACL verification in this arrangement, so ACL changes apply after the next sync. The implication is that changing permission metadata and making that change effective in retrieval are separate events. The supplied evidence gives no sync interval or revocation-latency guarantee.
AWS also notes that ACL mistakes do not return errors: affected documents are silently omitted from results. Missing retrieval results can therefore reflect an access-metadata problem. As an operational inference, investigating document availability requires checking both search behavior and ACL ingestion; the absence of an error does not establish that the permissions were configured as intended.
Query behavior differs according to the data source’s configuration. A request without userContext returns no documents from an ACL-enabled data source. Documents from a data source without ACLs enabled, however, are returned to all users, whether or not the request includes user context. Supplying verified identity alone therefore does not make every connected source subject to per-user restrictions.
The gateway’s connector calls the search API using its execution role. In the layered architecture, the knowledge base’s resource-based policy restricts searches to that role, and ACL awareness then returns only chunks from documents available to the identified user. Infrastructure access determines who can invoke retrieval; document ACLs determine which material the end user can receive.
The result is a conditional design rather than a blanket security guarantee. Its access boundary depends on verified token claims, enforced identity injection, appropriate document ACLs, synchronization, and control of alternate search callers. AWS supplies a concrete pattern for connecting those parts. The essential question for a shared enterprise assistant is whether every route to retrieval preserves that connection between the authenticated user and the documents the agent can use.