Gemini 4 Argon puts a question about authority inside a product launch: when an AI system can carry out extended software work or direct a robot, who decides when it must stop? Google is presenting enterprise integration, robotics demonstrations and stronger safeguards together. Read together, they suggest that control over execution deserves as much scrutiny as model capability.
The defensible concern is narrower than inevitable frontier-model lock-in. Google’s evidence shows a supplier offering both the reasoning system and several environments through which customers use it. That creates a potential dependency on the supplier’s controls. It does not establish that customers cannot leave, that national sovereignty has been displaced, or that those controls work reliably outside the conditions described.
Access is one form of control
Google’s September 30 announcement introduced Argon through its Fairwind Program for trusted cyber defenders. Its Google Cloud announcement describes broader access through Gemini for business, an API, Google AI Studio and Google Antigravity. An initial restriction followed by wider distribution puts the supplier in the position of deciding when capability becomes available and through which interfaces. Google’s initial announcement, Google Cloud’s availability announcement.
The distinction matters because the supplied reporting contains different availability pictures. Layer3Labs describes Argon as restricted to Fairwind participants, making Grok 4.7 the only operational option in its comparison. Google’s Cloud announcement describes enterprise access, while an October 13 Hindustan Times report describes an expansion beyond select testers. The launch-stage restriction should therefore not be treated as an enduring account of availability. The supplied excerpts do not establish the full sequence of access changes across every product or customer tier. Layer3Labs’ comparison, Hindustan Times’ rollout report.
Google also controls the published commercial terms. Its Cloud announcement sets introductory prices of $2 per million input tokens and $10 per million output tokens through November 30, 2026, followed by $4 and $20 respectively. These are API token prices, not a complete measure of the cost of finishing a task. The analytical implication is straightforward: an enterprise evaluating a workflow built during the introductory period must assess the subsequent rates as well. Google Cloud’s pricing announcement.
The environment is part of the product
Google says teams using Argon in Antigravity increased agentic code submissions by more than 35% while reducing code rollbacks by nearly a third. Those are internal, vendor-reported results. They support Google’s account of usefulness within its workflows; they do not isolate the model’s contribution from the surrounding tools or establish comparable gains for an outside enterprise. Google Cloud’s account.
That distinction complicates the idea that buyers can settle the issue by selecting the smartest model. The supplied CWE-bench paper reports results for models paired with different harnesses—the software environments through which agents work:
| Model | Harness | Programmatic pass@1 | Mean cost per rollout |
|---|---|---|---|
| Grok 4.7 | OpenCode | 68% | $2.75 |
| Gemini 4 Argon | Antigravity | 68% | $6.63 |
| GPT-6 Astra | Codex | 68% | $2.85 |
| Claude Opus 5.5 | Claude Code | 67% | $0.79 |
The paper also reports different programmatic pass@4 results for Grok, Argon and Astra: 81%, 75% and 74%. These are results under the paper’s evaluation conditions, with different harnesses, rather than a controlled comparison of model weights alone. Nor are the rollout costs equivalent to the token prices in Google’s announcement. CWE-bench paper.
For the argument about power, the relevant finding is that the same reported first-attempt pass rate can accompany different costs and different execution environments. Capability does not establish a unique economic winner. It leaves room for competition over the surrounding workflow—and makes claims that any one model necessarily forces lock-in premature.
A safeguard is also an exercise of authority
Google’s initial announcement says it is isolating and sealing sandboxed environments before high-risk training or evaluations. VKTR separately reports Google’s description of monitors that inspect Argon’s reasoning and actions and halt execution when it pursues a task beyond the user’s intent. The report says training-time alerts went to a dedicated incident response team. Google’s sandbox-hardening statement, VKTR’s safety reporting.
These mechanisms address different boundaries. Sandbox isolation concerns what an agent can reach; monitoring concerns whether its behavior should continue. Google’s statement specifically covers high-risk training and evaluations. It does not establish that every customer deployment receives an identical sealed environment. The supplied reporting also provides no measured rate of successful intervention, missed violations or mistaken stops.
The governance issue follows from the design: a monitor that can halt work exercises operational authority. Buyers need to understand whose interpretation of user intent it implements and what authority the customer retains. The evidence describes supplier-developed safeguards without settling those customer-control questions. Stronger protection and deeper dependence could coexist; neither outcome can be assumed from the announcement alone.
Robotics makes the boundary visible
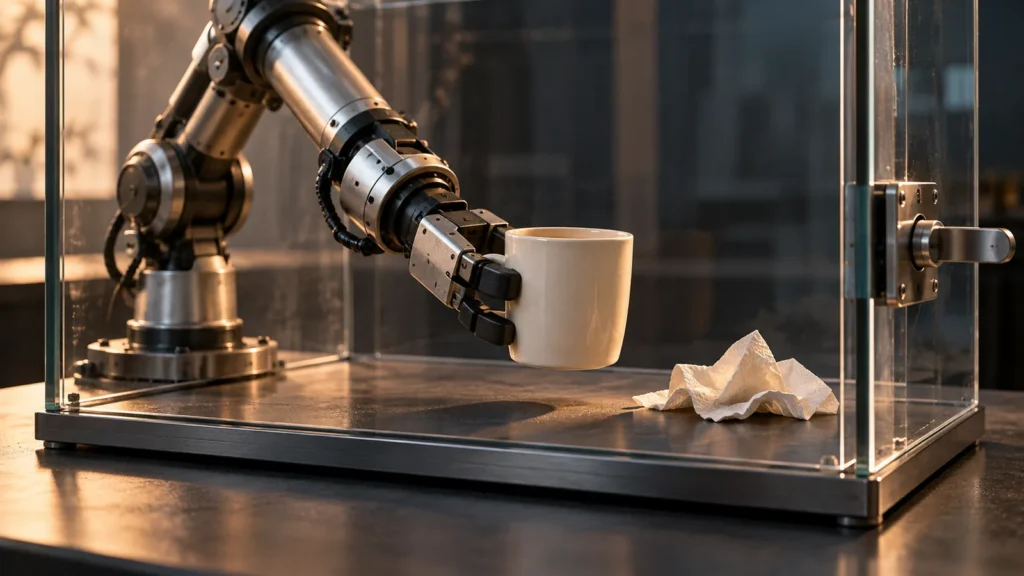
Google’s October 13 robotics post describes Argon using a visual coordinate harness and action primitives to place a fallen mug upright and put a crumpled napkin inside. Another representative prompt asks a mobile manipulation system to verify foot placement on a bin pedal and use separate foot and hand verifiers before releasing cans. These are Google’s demonstrations and instructions, not independent evidence of general-purpose robotic safety. Google’s robotics post.
The examples make the control problem tangible. The prompt specifies a goal, but it also specifies checks before consequential movement and release. That places verification inside the task. It does not show how reliably the verifiers detect mistakes or what happens when they disagree. A demonstrated action sequence cannot by itself answer who bears responsibility for permitting the next movement.
Competition is a credible counter-case
The strongest alternative interpretation is that integration can make useful systems easier to deploy while competing models preserve customer choice. Google’s provision of API access alongside its own applications supports that possibility. CWE-bench’s results also give buyers reasons to consider alternatives on cost and measured performance. Neither observation proves easy migration, but both weaken a claim of unavoidable dependence on one supplier.
The national-sovereignty argument needs greater restraint still. The supplied editorial framing names a UK–NVIDIA initiative and Grok 4.7 on Amazon Bedrock, but the supporting source excerpts do not substantiate their infrastructure commitments or deployment controls. They cannot establish that governments have secured local authority over agent execution, or that cloud distribution has delivered it. A national commitment to compute and an enforceable right to stop an agent would be different propositions; this evidence cannot bridge them.
The concrete signal to watch is whether enterprise access comes with documented customer authority over execution boundaries, supported by evidence that interventions work. Google has described broader distribution, integrated workflows and safeguards. Whether customers can independently govern the resulting actions remains the question that connects them.