Introduction to the DGX Spark Developer Kit
NVIDIA has introduced the DGX Spark Developer Kit at SC26 in Chicago, presenting a four-system desktop cluster as a local platform for scientific computing, AI models and agents. Its central proposition is control over development time: researchers can build, test and debug workloads at their desks, reserving shared computing resources for production runs instead of joining a queue for every experiment.
According to NVIDIA’s announcement, the kit is available for sale, while an installation playbook for the NVIDIA HPC SDK is still coming soon. That distinction matters. The hardware offering and the forthcoming scientific-software deployment guidance are separate parts of the announcement; researchers should not read the launch as confirmation that the playbook is already available.
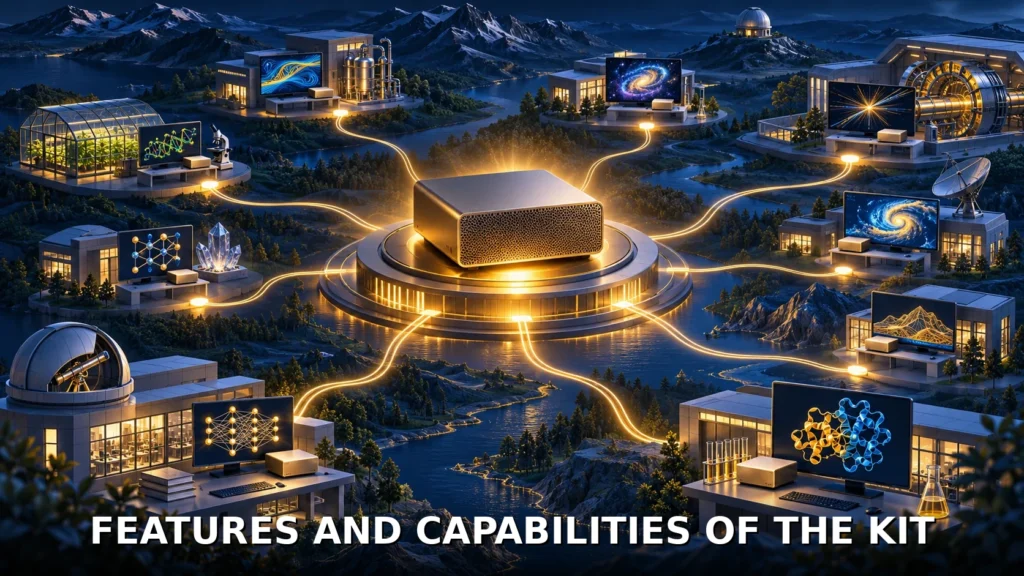
The intended audience includes researchers, academics and developers working on multi-node scientific applications. NVIDIA describes a system that scales from one DGX Spark node to four, using direct networking between the machines. The four-node configuration offers 512GB of combined memory and 20TB of NVMe storage, with the GB10 Grace Blackwell Superchip providing the computing foundation.
The strongest case for this kind of local supercomputing is therefore a workflow argument. A researcher may gain useful time by avoiding a shared-cluster queue, even when the eventual production workload belongs on a larger system. NVIDIA’s examples support that distinction, but they do not establish that the kit replaces a supercomputer or delivers a particular speedup across scientific applications. The evidence here comes from NVIDIA’s own account, including its descriptions of customer and laboratory work.
Features and capabilities of the kit
The kit connects each DGX Spark system directly to its two neighbors in a ring through NVIDIA ConnectX-7 networking. NVIDIA says this arrangement requires no network switch to purchase or configure. It makes the connections between the four machines a defined part of the offering, rather than leaving researchers to assemble an unspecified cluster network.
The announcement identifies several concrete capabilities and one significant pending component:
| Component | What NVIDIA documents | Qualification |
|---|---|---|
| Cluster | One to four DGX Spark systems; a four-node ring configuration | The announcement supplies no application-by-application scaling results. |
| Networking | Direct NVIDIA ConnectX-7 links between neighboring nodes | No separate network switch is required. |
| Capacity | 512GB of combined memory and 20TB of NVMe storage at four nodes | These are cluster totals. |
| Model deployment | Up to 700B parameters locally with NVFP4, citing DeepSeek V4.1 | This is NVIDIA’s deployment claim, not a reported throughput measurement. |
| Scientific development software | NVIDIA HPC SDK installation playbook | Described as coming soon. |
The capacity figures explain why NVIDIA positions the kit for distributing models and scientific workloads across multiple systems. They do not, by themselves, show how quickly a particular application will run. The announcement does not provide a common benchmark suite or a scaling curve comparing one, two and four nodes, so the configuration is more clearly specified than its performance across workloads.
There is also an ambiguity in the model-size claim. NVIDIA describes the kit throughout as four systems or nodes, but the sentence about deploying models with up to 700B parameters refers to “four DGX Spark clusters.” The surrounding architecture description points to the four-system kit, yet the supplied account does not clarify that wording. Researchers should treat the 700B figure as an attributed NVIDIA claim with NVFP4 specified, rather than an independently established capacity result under fully documented conditions.
For scientific application development, the forthcoming NVIDIA HPC SDK playbook is a substantial part of the proposition. NVIDIA says it will bring GPU-accelerated C, C++ and Fortran compilers, libraries and message passing interface tools to the cluster. These are the same development tools used on NVIDIA-powered supercomputers, according to the company. The intended workflow is to build and test across four nodes, examine how computation and data are distributed, and debug communication before moving to larger systems.
NVIDIA distinguishes demonstrated four-system workloads from broader community validation. Its four-system examples include LAMMPS with Kokkos for materials simulation and NAMD for molecular dynamics. Separately, it says the DGX Spark community has validated GROMACS, OpenFOAM and WRF, alongside NVIDIA NIM microservices such as OpenFold3 and Boltz-2. Those statements should retain their different scopes: community validation on DGX Spark is not, on the supplied evidence, a four-node performance result for every named application.
The announcement also describes open dataset and post-training recipes for Nemotron 3.5 Super VL running on DGX Spark, intended to help researchers adapt the model for life sciences and chemistry. This broadens the software story beyond simulation alone. It does not establish that all the named applications, models and recipes arrive as one preconfigured environment with the developer kit.
Impact on research and development workflows
NVIDIA’s clearest argument is that local access can shorten the interval between an idea and a result. Teams with fixed compute and server allocations can develop and debug locally, preserve server hours for production work, and keep unpublished results and proprietary datasets on premises. The practical value depends on how much of a team’s development cycle fits the local system and how much time it currently loses waiting for shared resources.
The Rubin Lab at IGI at the University of California, Berkeley provides NVIDIA’s most explicit turnaround example. The lab uses a DGX Spark with NVIDIA’s Evo 2 model to predict bacterial traits from genome sequences, comparing embeddings from genomic and protein language models against classical baselines. NVIDIA reports that results arrived 15x sooner without an 11-hour cluster queue.
That is a meaningful reported improvement in elapsed time, but its scope needs care. The account ties the outcome to avoiding the queue; it does not establish a 15x increase in hardware execution speed. It also concerns a DGX Spark deployment, rather than a documented four-node developer-kit benchmark. For a researcher deciding whether to work locally, the useful lesson is that access delays can materially affect turnaround, while the size of any benefit remains workload- and allocation-dependent.
A second Berkeley example concerns longer, repeated training work. NVIDIA says the Hartwig Group uses a DGX Spark for LoRA fine-tuning of the Nemotron 3 Super 120B-A12B model for chemistry machine learning, training a prediction head on experimental values. With NVFP4 quantization, the group reportedly fit a 120B-class model on one device and avoided multi-day cluster queues, running eight- to 24-hour training fits back-to-back.
This example makes the scheduling argument concrete in a different way. Local capacity can support a sequence of extended experiments without a fresh wait for shared access between runs. It does not demonstrate the performance of that model across four nodes, and the announcement supplies no controlled comparison of training quality or execution time. Its evidential value is the reported feasibility of the laboratory’s local workflow under the stated model and quantization choices.
Other examples illustrate the range of work NVIDIA associates with DGX Spark. Kvantify reports using NVIDIA cuQuantum for tensor-network simulations of quantum-chemistry circuits with up to 70 qubits and 975 gates on a single DGX Spark, using circuits generated for penicillin ground-state energy calculations. CYRAN AI, an IIT Delhi spin-out, uses DGX Spark and its PixelFlux library to accelerate JPEG 2000 decoding of large satellite images for local geospatial analysis. OpenFold’s example concerns fine-tuning OpenFold3 to improve protein-ligand structure predictions for drug discovery.
These are distinct application accounts, not interchangeable benchmarks. The quantum-circuit figures describe a particular reported simulation; the satellite-image and protein-ligand examples identify different workloads without supplying comparable performance measurements. Taken together, they show the breadth of NVIDIA’s local-computing case, while leaving researchers to establish suitability for their own applications.
The agent component is similarly specific. NVIDIA describes researchers exploring agent-assisted workflows that prepare simulation inputs, launch runs and summarize results, with scientists validating both setup and conclusions. The documented role is assistance within a supervised scientific process. The announcement does not provide a named agent framework, an accuracy evaluation or a deployment procedure that would establish a ready-made autonomous research system.
NVIDIA also describes training AI models that approximate slow simulations and using them to refine wing designs toward minimum drag. Its example involves narrowing a 10-million-cell simulation to the 50–500 dimensions that matter before committing supercomputer time. The announcement presents this as a workflow researchers can pursue, without a detailed evaluation establishing accuracy or general applicability. The relevant analytical point is the proposed division of labor: explore and refine locally, then use larger infrastructure for the work that still requires it.
For multi-node development, that division extends to debugging. NVIDIA says teams can examine distribution of computation and data and resolve communication issues on four nodes before scaling up. This gives the kit a role beyond running smaller production jobs: it can serve as a local development platform. The supplied evidence does not show that behavior on four nodes predicts performance at larger scales, so successful local testing remains distinct from validation on the eventual target system.
Availability and purchasing options
NVIDIA says the DGX Spark Developer Kit is on display at SC26 and available for sale. DGX Spark products and cables can be purchased through NVIDIA Marketplace and OEM partners, including Acer, ASUS, Dell Technologies, GIGABYTE, H3C, HP, Lenovo, MSI and xFusion. The supplied announcement identifies those channels but does not specify prices, regional stock or delivery times.
It also does not provide a detailed purchasing breakdown establishing which components every partner bundles together. That leaves the precise configuration and included cabling to be confirmed through the purchasing channel. The announcement’s statement that no network switch is required is clear; it is not a complete itemized commercial offer.
The NVIDIA HPC SDK playbook remains the other availability question. NVIDIA says that, once available, it will provide guidance for building and running the SDK, developing multi-node GPU applications, exploring FP32 and mixed-precision algorithms, and running molecular dynamics and materials simulations with LAMMPS with Kokkos before scaling to data center systems. No release date for that playbook is supplied.
For prospective users, the decision turns on a concrete match between workload, access constraints and software readiness. The announcement supports a case for local iteration, reports examples of laboratories avoiding substantial queue delays, and specifies a four-node platform for scientific development. It leaves pricing, detailed performance comparisons and the playbook’s delivery unresolved. Researchers can assess the kit against those boundaries: which experiments can move to the desk, which software steps remain pending, and which production runs still belong on shared infrastructure.