Introduction – why local AI matters for agents
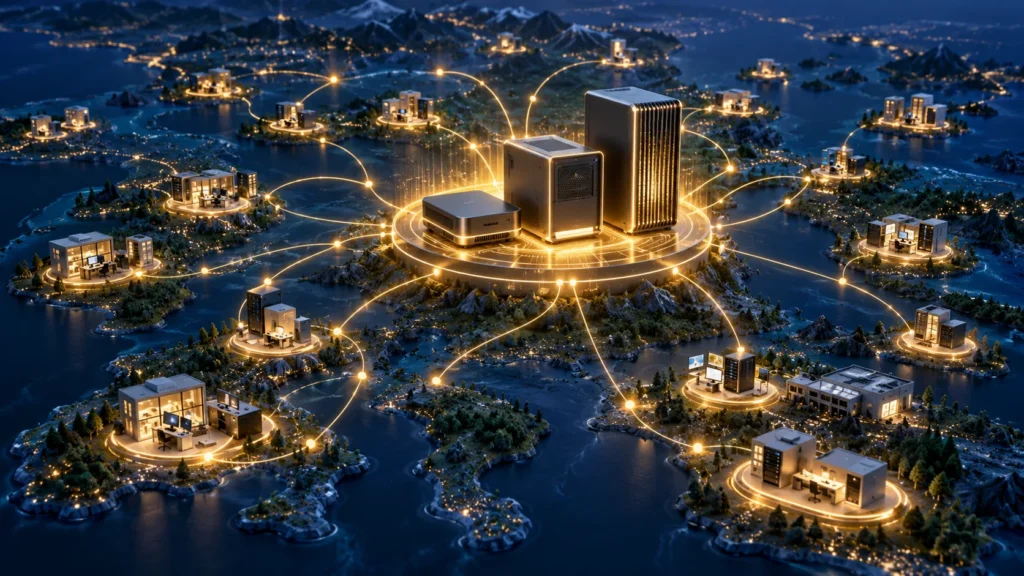
NVIDIA is positioning local AI hardware as a platform for agents across personal computers, developer systems and enterprise workstations. At GTC Berlin, the company showcased RTX Spark, DGX Spark and DGX Station alongside coding models, inference optimizations and tools for sharing local compute. The central proposition is that agents can run where users and teams work, with more control over the systems handling their data.
The announcement spans more than hardware. NVIDIA describes desktop agents, model launchers, enterprise management integrations and shared inference endpoints. Together, these address different parts of deployment: running a model, connecting it to applications and making it accessible to a team.
That is a more specific development than a wholesale shift away from cloud infrastructure. NVIDIA’s October 21 announcement establishes its local deployment strategy, but supplies no independent evidence of widespread customer migration. Its performance and privacy claims also need to be read in the context of the particular models, software and hardware described.
Overview of NVIDIA’s local AI hardware lineup
NVIDIA divides the lineup by operating environment and intended user. RTX Spark targets personal agents on Windows PCs. DGX Spark supports developers building and scaling applications on Linux. DGX Station addresses enterprise teams running what NVIDIA calls frontier workloads on Linux, with Windows systems expected from partners in December.
| Platform | Main audience and environment | Announced emphasis |
|---|---|---|
| RTX Spark | Personal users and agent developers on Windows PCs | Local desktop agents, content creation and customizable systems |
| DGX Spark | Developers and small teams on Linux | Local model development, clustering and model launch tools |
| DGX Station | Enterprise teams on Linux; Windows version planned | Larger models, shared inference and enterprise management |
These categories describe different deployment needs rather than a demonstrated ranking of agent quality. The announcement does not provide a common benchmark comparing all three platforms. It instead presents hardware capacity, software support and examples of workloads appropriate to each.
Availability also varies. RTX Spark had launched on October 16. The announcement scheduled partner rollout of DGX Spark 64GB systems for October 23 and described Linux DGX Station systems as already shipping. Other features, including the Windows Station and some software services, remained forthcoming when the announcement was published.
RTX Spark: personal agents on Windows PCs
RTX Spark is the most personal end of NVIDIA’s local AI strategy. NVIDIA lists up to 128GB of unified memory and 1 petaflop of AI compute, alongside accelerated content creation and gaming. Those capacity figures describe the platform; they do not establish how quickly a particular agent will complete a task.
The more direct agent development is Underdog, a desktop application NVIDIA says is available for RTX Spark. Powered by its Husky model-specific inference engine, Underdog runs models entirely on the device. NVIDIA presents this as a way for personal agents to work without user data leaving the PC.
That privacy claim concerns the described application and its local execution. It should not be generalized into a guarantee covering every agent installed on RTX Spark. The relevant distinction for a prospective deployment is whether its chosen application actually follows the same local processing model.
NVIDIA also says many RTX Spark laptops have unlocked bootloaders to support developers and enthusiasts customizing local agents. In its keynote demonstration, agents on RTX Spark helped train Hugging Face’s Microduck robot using NVIDIA Isaac Lab, Hermes Agent and Nemotron 3.5 Bolt 74B. The demonstration connects personal agent hardware with robotics development, though the announcement does not supply a measured comparison with another training setup.
DGX Spark: developer‑focused Linux platform
DGX Spark extends the local model approach to Linux development and small teams. NVIDIA says the new 64GB systems can run models including Nemotron 3.5 Bolt 74B 24GB, Qwen3.8 27B and Gemma 4 26B-A4B. These are named compatibility examples, not evidence that every model or context length will fit every configuration.
For larger workloads, developers can connect systems through built-in NVIDIA ConnectX-7 networking and NVIDIA Sync Cluster Assistant. The announcement says manual configurations support up to eight DGX Spark units, enabling larger models, longer contexts, concurrent agents and distributed development. It describes a configuration with 1TB of unified memory that can run models such as GLM 5.3.
The source separately discusses 64GB systems and the 1TB cluster without specifying the complete memory configuration behind that cluster figure. Buyers should therefore avoid treating 1TB as the capacity of any arbitrary eight-unit arrangement.
NVIDIA Sync Model Launcher, scheduled for later in October, is intended to simplify setup on a single system or cluster. NVIDIA says it downloads a model and container suited to the configuration, connects the model to OpenCode and loads DGX Spark Skills for troubleshooting, maintenance and documentation guidance.
The October software update also adds a Wi-Fi Assistant for switching networks in appliance mode. These changes address setup and maintenance alongside model execution. For a team sharing one model backend across concurrent development sessions, those operational details are part of whether local infrastructure is practical.
DGX Station: enterprise‑grade frontier workloads
DGX Station brings larger capacity and enterprise administration into the lineup. NVIDIA specifies 748GB of coherent memory and up to 20 petaflops of AI performance. It says the system can run models such as GLM 5.3 and serve more than 30 users at speeds comparable to cloud models. That comparison is a vendor claim: the announcement does not identify a cloud baseline or provide enough methodology to evaluate equivalent service quality.
Seven new integrations connect DGX Station with Absolute Security, Splunk by Cisco, Fleet Device Management, Microsoft Intune, Perforce Puppet, Progress Software Chef and Tanium. NVIDIA says these help IT teams apply enterprise setup, management and conformity processes. NVIDIA Sync also adds support for connecting two Linux-based DGX Station systems.
The planned Windows version targets workflows combining professional applications on NVIDIA RTX PRO GPUs with agents whose language models run on NVIDIA GB300 systems in the same machine. NVIDIA names manufacturing application support from companies including Dassault Systèmes, MathWorks and Siemens, and agent options including Hermes Agent, Perplexity and Aible. These are announced capabilities for upcoming systems, rather than evidence of completed enterprise deployments.
Robotics is another focus. NVIDIA released three open source reference workflows involving GPT-6 Astra, Isaac Lab, Isaac Lab-Arena and Cosmos. The described tasks include refining GR00T 1.7 models with reinforcement learning, training dexterous manipulation skills and post-training Cosmos world models for synthetic data generation.
NVIDIA Cloud Functions is also planned in early access for Linux DGX Station. Teams would register local model endpoints in a shared catalog and access them through one OpenAI-compatible entry point. NVIDIA says this lets developers change the model behind an endpoint without changing application code, while colleagues use shared models without direct machine access. The resulting deployment model is a team inference service under local control.
New models and software tools (Recursive Flint, Day‑0 model support)
Recursive Flint provides a coding-focused example of the software accompanying the hardware. Released by Recursive Superintelligence, it is a 40-billion-parameter mixture-of-experts model with 2.5 billion active parameters. NVIDIA says it performs well on SWE-Bench Pro v2, Terminal-Bench 2.1 and SWE-bench verified, but the announcement gives no scores. Those references cannot support a quantitative ranking against competing coding models.
NVIDIA says Recursive’s Eureka Machine automated a research loop of proposing ideas, implementing them, running experiments and selecting subsequent work. The resulting specialized kernels reportedly increased Flint’s generation speed on RTX Spark by 55% without changing its weights. This is a reported generation-speed improvement, not a demonstrated 55% reduction in complete coding-task time.
Flint’s open weights are available on Hugging Face under Apache 2.0. The announcement lists support for RTX Spark, DGX Spark, GeForce RTX and RTX PRO GPUs, plus post-training through NeMo Automodel and NeMo RL.
Day-zero support covers models from NVIDIA Nemotron, GLM, DeepSeek, Qwen, MiniMax and Liquid AI, as well as Black Forest Labs’ image model. NVIDIA describes MiniMax M3.1 Flash as bringing long-context AI to DGX Station and DGX Spark. Liquid AI’s LFM2.5-24B-A2B activates 2 billion of its 24 billion parameters per token and is presented as suitable for private, tool-calling agents on PCs.
Some naming is inconsistent within the announcement. It refers to the small Nemotron model as both “Nemotron Bolt E4B 4B” and “Nemotron Bolt E4B 4GB,” while its image-model references include “FLUX.3 Klein” and “FLUX 3 Image Klein.” These differences should be preserved as source ambiguities rather than treated as proof of distinct versions. The broader supported point is that NVIDIA is pairing local hardware with support for conversational, coding, reasoning and image workloads.
Performance enhancements (llama.cpp, vLLM, optimized checkpoints)
NVIDIA reports improvements in two open source inference engines, with different models and hardware involved. The figures require separate treatment because they measure different workloads and metrics.
| Engine or platform | Model and hardware | NVIDIA’s reported improvement |
|---|---|---|
| llama.cpp | Qwen 3.8 Flash Next on RTX PRO 6000 Blackwell | End-to-end agentic tasks up to 1.4x faster |
| vLLM | Qwen3.8 27B on DGX Spark | Agentic tasks up to 1.3x faster |
| DGX Station | GLM 5.3 Flash | Up to 1.2x higher throughput |
The llama.cpp change adds speculative decoding support with MTP. For vLLM, NVIDIA cites faster speculative decoding and new FlashInfer prefill kernels for Qwen’s linear-attention layers. The announcement does not provide the full test conditions or independent validation. These are configuration-specific, “up to” claims, not expected gains for every agent.
Memory efficiency receives separate attention through optimized model checkpoints. NVIDIA says these are quantized while remaining close to full-precision accuracy, leaving memory available for KV cache. The first examples are Qwen3.8-Flash-Next-FP4-Local on one DGX Spark 128GB or RTX PRO 6000, and GLM-5.3-Flash-FP4-Local on two systems.
The source does not quantify the accuracy difference. Its practical claim is that reducing model memory requirements can leave room for execution needs beyond the weights themselves. Model fit and usable working capacity therefore need to be evaluated together.
Implications for AI agent deployment and privacy
The clearest implication is a broader set of local deployment choices. An individual can use an on-device desktop agent, developers can share a DGX Spark cluster, and an enterprise team can organize DGX Station around managed applications or shared model endpoints. Local AI here includes both personal computing and infrastructure shared within a team.
Privacy is a motivating benefit, but the evidence supports specific claims rather than blanket assurances. Underdog is described as keeping model execution and user data on the PC. DGX Station is presented as enabling on-premises agents and locally controlled inference. The announcement does not provide an independent security assessment or establish that every supported application keeps every part of a workflow local.
Likewise, local hardware is positioned as reducing dependence on shared infrastructure, but no measured latency or cost comparison establishes a universal advantage over cloud services. The decision depends on the required model, concurrency, application support and operating environment. NVIDIA’s management integrations and launch tools are relevant because deploying an agent also involves administering the system that serves it.
Conclusion – the future of on‑device AI agents
NVIDIA’s GTC Berlin announcement presents local agents as a systems problem: hardware capacity, model availability, inference software, application access and administration all matter. RTX Spark, DGX Spark and DGX Station address different combinations of those needs.
The evidence supports an expanding local deployment toolkit, with several capabilities still scheduled or entering early access. It does not establish universal performance superiority or a completed move away from cloud AI. For developers and enterprises, the useful next test is whether a specific model and agent workflow delivers the required quality and capacity within a controllable local environment.