Greptile GPT-6 Astra testing turns code review into something closer to a real user session. Instead of only reading a pull request, an agent starts the application, drives it through a browser, and watches what actually happens on screen. The approach was described in an OpenAI case study published on 26 October 2026, which presents Greptile as a startup using three OpenAI products together: GPT-6 Astra to test user workflows, Daybreak to strengthen security, and Codex to reduce rework.
Greptile moves bug detection beyond code review
Greptile builds AI agents that review and test code changes with full context of the codebase. Its co-founder and CEO, Daksh Gupta, puts the mission plainly:
“We are in the business of reducing bugs and making the world’s software more reliable.”
That mission has two halves. The first is reading code well: understanding what a change does, what it breaks, and whether it matches the intent behind the pull request. The second is testing behaviour: finding out what the application actually does when it runs. The OpenAI case study is about the second half becoming automated at scale, with GPT-6 Astra’s computer-use capability doing the driving.
The timing matters. Teams now ship code far faster than they used to, much of it written with AI assistance, and the review step has to keep up. Gupta’s argument is that the old way of closing the behaviour gap does not scale:
“A QA firm testing all of your changes is just impractically slow considering how fast we’re able to ship code with these models.”
How Greptile GPT-6 Astra testing works
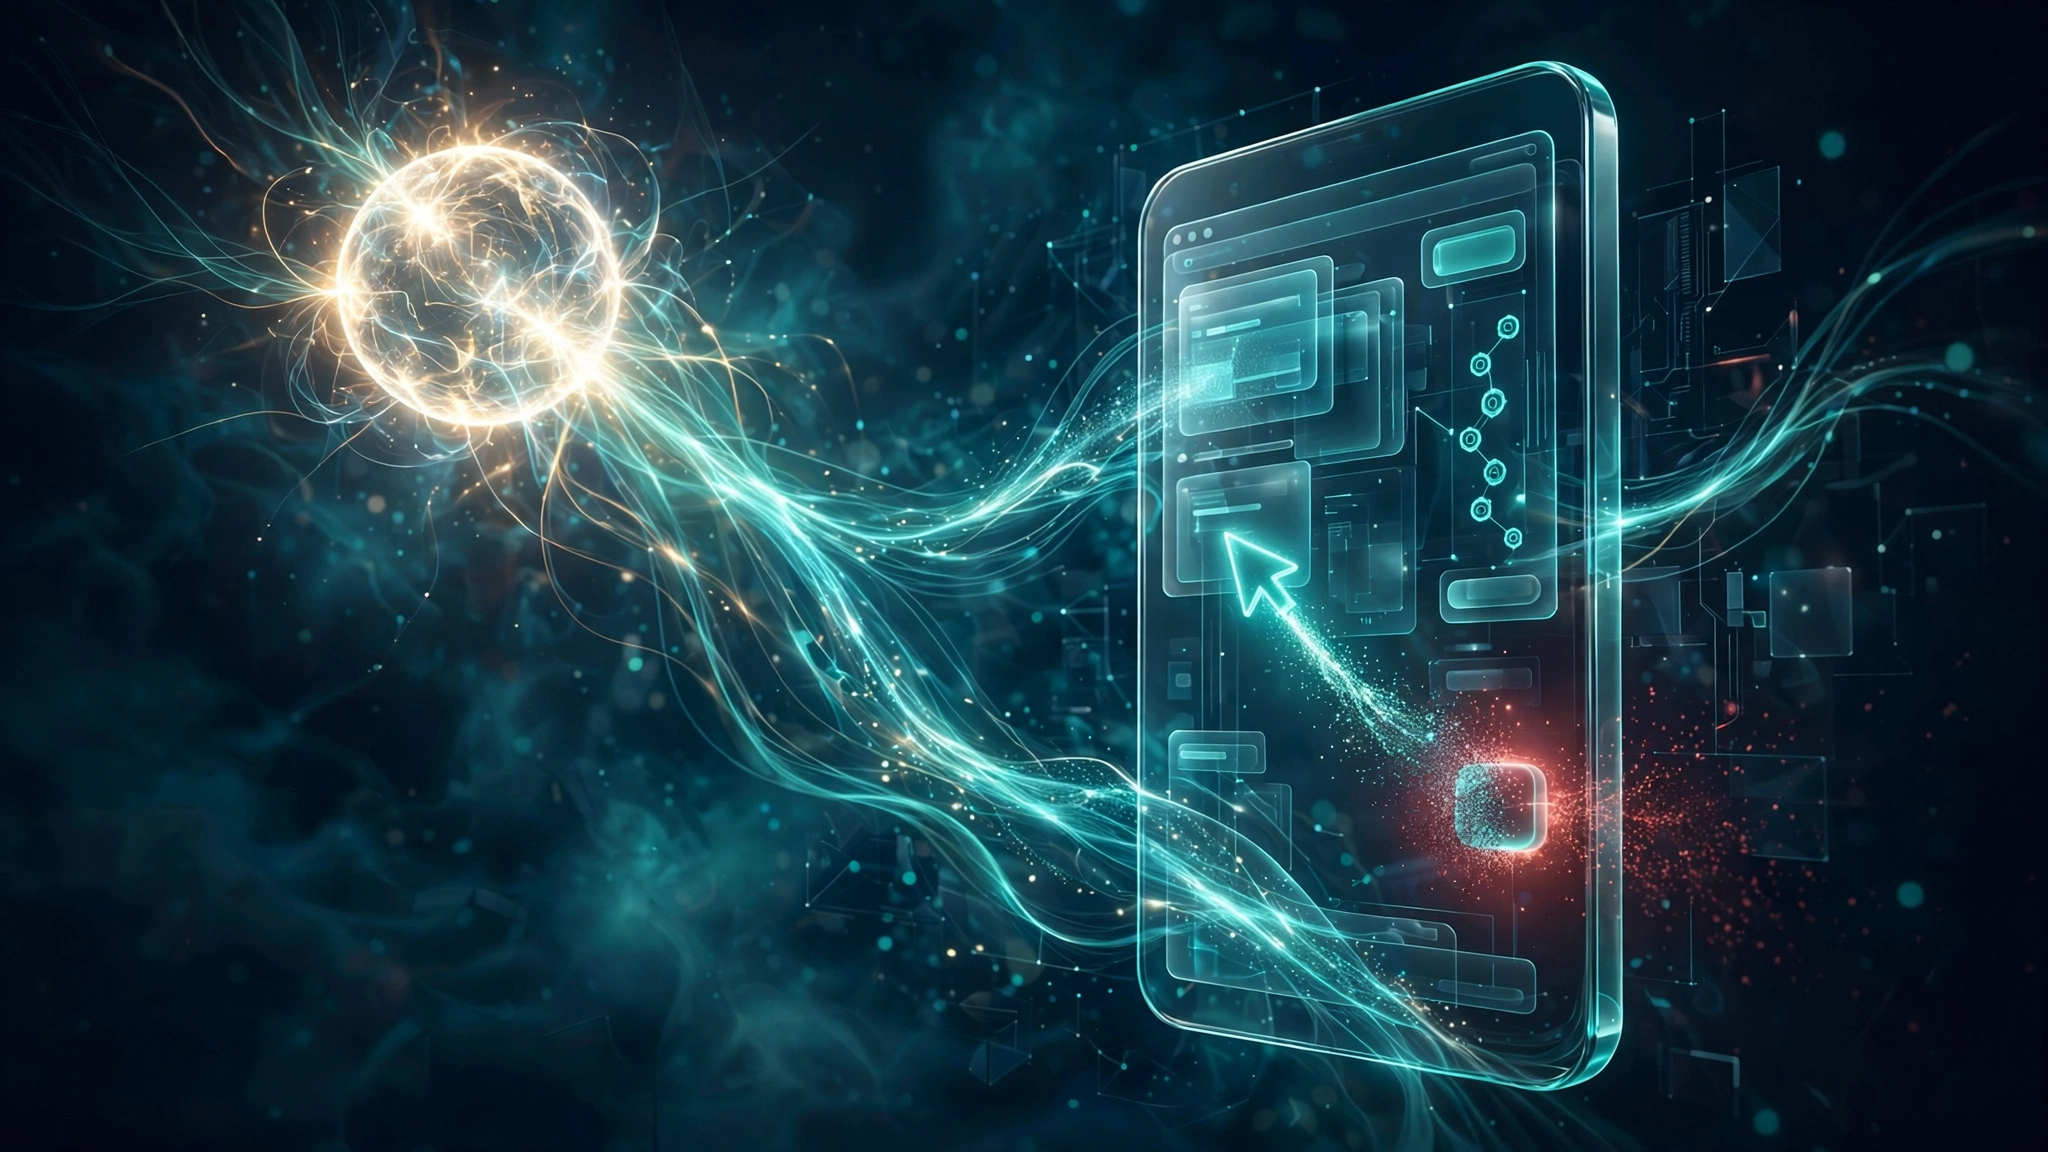
The workflow starts where a pull request starts. Greptile can start a development server for the pull request, then use GPT-6 Astra to act as a user: resizing the browser to an iPhone-sized viewport, moving through the application, and using the model’s visual understanding to inspect what appears on screen. The point is to catch the failures that only exist in a running application, in the exact conditions a user would meet them.
The case study gives a concrete example. A button disappears when a website is viewed on an iPhone. Nothing in the code, read line by line, obviously announces the problem; the layout only fails at that viewport size, in that interaction. An agent driving the application at an iPhone-sized viewport sees the missing button and reports it. That is the whole idea in one scene: the test is the user’s experience, reproduced automatically.
Gupta describes the shift this way:
“For the first time ever, computer use is in a place where you can automate the experience of having a user try to break your application and allow large companies to ship much more confidently.”
GPT-6 Astra is the model doing that driving. OpenAI and Google Cloud position it for demanding coding, computer use, professional tasks and scientific research, and OpenAI’s announcement says it “brings together” years of work across pre-training, reinforcement learning and alignment to dominate computer-use tasks, software engineering, mathematics and enterprise workflows. On OSWorld 2.0, a benchmark of computer-use workflows, Astra was reported at 72.6% on the offline set, against 65.7% for GPT-5.6 Sol, according to a TokenPost report of the results. That benchmark awards partial credit for incomplete task progress, so the number is a signal about capability, not a count of tasks finished end to end.
Why running the application beats reading the code
Validating a pull request means checking several things at once: whether the code is logically correct, whether it does what the developer intended, whether it is secure, and whether it breaks existing functionality. Some of that can be settled by reading. Some of it can only be checked by running the application — a layout that collapses at one viewport size, an endpoint that returns an error under real traffic, a component that breaks on a specific screen size. The diff looks clean. The code compiles. Running the code can reveal problems that reading alone might miss.
Greptile’s own engineering writing states the ceiling directly:
“Static review has a ceiling. It can reason about what the code says, not about what it does.”
Greptile already had an execution layer before this announcement. TREX, short for Test, Run, Execute, launched on 15 June 2026. When the core reviewer spots behaviour worth testing, a TREX agent creates a sandbox, generates targeted tests for the changes plus edge cases, and runs them against the actual services, dependencies and frameworks in the repository — no mocks. Results come back with proof: logs, screenshots, API traces, execution scripts, and sometimes a short video of the UI interaction, attached to the pull request comment.
Greptile’s internal evaluations found that adding the execution layer caught 20% more bugs than the base reviewer alone, with most of the additional catches requiring the code to be run. That figure comes from Greptile’s own evaluation, not an independent study, and the company charges $2 per TREX run after a free beta period. One thing the sources do not state is whether the GPT-6 Astra testing workflow described in the OpenAI case study is the same system as TREX or a separate workflow, so the two should not be treated as one thing.
The review side itself is built on whole-codebase context. Greptile builds a graph of the entire codebase — files, functions, dependencies — and reviews each change against that context, so it can trace how a change ripples through distant parts of the system. Each pull request gets a 0–5 confidence score so a team can see at a glance how safe it is to merge, and each comment carries a one-click fix button that hands the issue to Claude Code, Cursor, Codex or Devin.
Strengthening defences with Daybreak
The second part of the announcement is security. Gupta’s point is that more powerful models cut both ways: they also make it easier for attackers to exploit applications, putting companies at risk, including companies that previously would not have been typical targets. The case study positions Daybreak as a way to make it easy even for a startup to secure its systems.
Daybreak is OpenAI’s trusted-access programme for cyber defence. It comes in tiers. Daybreak Blue gives reduced refusals on supported mainline models for verified defensive work in authorised environments — vulnerability triage, secure code review, malware analysis, detection engineering, incident response and patch validation. Daybreak Red adds cyber-specialised models for authorised penetration testing and red teaming. GPT-6 Astra retains its standard safeguards in Blue, with reduced refusals available in Red, and access to both tiers requires additional approval.
What the case study does not say is which Daybreak tier Greptile uses, so that detail should not be assumed. What it does establish is the shape of the argument: testing behaviour and testing security are presented as two halves of the same validation problem, and both are aimed at teams of any size, not only large enterprises.
Codex and the knowledge base: fewer reverts, less rework
The third part of the announcement is about writing code, not testing it. Greptile’s Knowledge Base indexes a company’s codebase and documents how it works in a form people and agents can read. That documentation is exposed to Codex through a Model Context Protocol (MCP) server, so Codex writes code that follows the customer’s existing patterns instead of inventing its own.
Thousands of customers have connected Codex to a Greptile knowledge base, according to Gupta. To measure the impact, the team tracks how often AI-generated code is reverted. When agents are given context, fewer reverts happen, and customers save time and save inference — savings they can put toward new work instead of reworking the same changes.
Greptile also uses Codex to build its own software and agents, with heavy usage across engineering in particular.
What this means for engineering teams
For a team shipping with AI assistance, the practical change is that behaviour testing can happen on every pull request rather than in periodic human QA passes. A review agent that reads the diff, an execution layer that runs the changed behaviour, and a computer-use agent that drives the application the way a user would are three different checks on the same change, and each can reveal problems the others might miss. Static review works from the code itself; execution runs the changed behaviour; and computer-use testing drives the application the way a user would, which can surface interaction and layout failures that only appear on screen.
The second implication is about rework. The Codex and Knowledge Base half of the announcement is about following the codebase’s own patterns: giving the coding agent the patterns to follow, so generated code needs fewer reverts and less rework. Fewer reverts means less of the team’s time spent redoing work that was already done once, which is where the saved inference and saved hours actually come from.
The third is about pace. If validation can keep up with generation, teams do not have to choose between shipping fast and shipping carefully. That is the promise Gupta is making: automated behaviour testing lets large companies ship much more confidently, and the same machinery is aimed at startups too.
Limits and open questions
There are real limits to what the sources establish. The OpenAI case study gives no public pricing, availability or performance figures for the GPT-6 Astra testing workflow itself — the $2-per-run figure belongs to TREX, and the 20% figure is Greptile’s internal evaluation, not an independent benchmark. Whether the Astra workflow and TREX are the same system is unstated, and the Daybreak tier Greptile uses is unstated too.
There is also a scope question the sources do not answer. Computer-use testing works from what appears on screen; whether it also catches failures that leave no visual trace — a wrong value written to a database, a race condition under load, a security flaw that never shows up in the UI — is not established by the sources. The case study describes behaviour testing, code review and security checks as parts of one workflow, and the honest reading is that each can reveal problems the others might miss; none of them on its own is the whole of validation.
Finally, Ultrafast — the future speed lever Gupta says he is most excited about — is framed as a way to move as fast as the team can come up with ideas, not as a shipped capability in this announcement. He puts it this way:
“I’m most excited about Ultrafast as a lever for us to move exactly as fast as we can come up with good ideas.”
His longer-term goal is to make changing and shipping critical enterprise software as easy as shipping a side project, with OpenAI helping Greptile build the validation that requires. On the evidence available, the validation side is the concrete part: an agent that reads the code, an agent that runs it, and an agent that drives it the way a user would — three checks that can each reveal problems the others might miss.