Introduction to the TPU 8tx launch and 8i Max
With the TPU 8tx launch and the introduction of TPU 8i Max, Google has added two configurations to its eighth-generation tensor processing unit portfolio, separating two priorities for AI infrastructure: protecting sensitive workloads while they run, and giving large inference workloads more memory resources. TPU 8tx targets confidential training and inference. TPU 8i Max combines two inference-focused TPU 8i chips in one package.
The distinction matters more than the shared generation number. An organization that needs proprietary data and model weights protected during processing faces a different infrastructure decision from one trying to serve models with very large context windows. Google’s new configurations address those requirements through different combinations of accelerator silicon, host processors, networking and packaging.
TechCrunch reports that both additions build on Google’s eighth-generation chips introduced in April 2026. TPU 8tx is based on the training-oriented TPU 8t and was designed with AMD. TPU 8i Max builds on TPU 8i, the inference-focused member of the family. These are extensions of an existing generation rather than evidence of two entirely new underlying chip designs.
That distinction also frames the launch’s strategic significance. Google is broadening what its own hardware can support, while keeping different workload requirements visible in its product lineup. The announcement supports a story about specialization within Google’s infrastructure portfolio. It does not, on the available evidence, establish a general performance advantage over competing accelerators.
The reporting provides useful architectural details but leaves important questions open. There is no pricing, general availability schedule or independent application benchmark in the supplied evidence. The two reports also disagree about the increase in TPU 8i Max memory capacity, a material qualification for anyone evaluating the larger package.
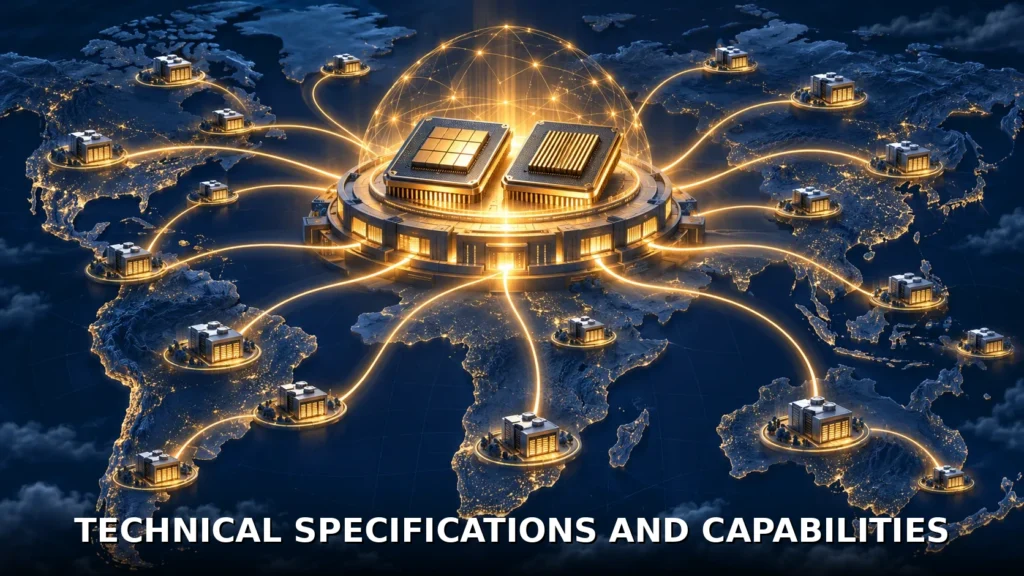
Technical specifications and capabilities
TPU 8tx combines existing accelerator silicon with a different system configuration. According to ServeTheHome’s account, it uses the same silicon as TPU 8t, paired with custom 5th Gen AMD EPYC Turin hosts. Its distinguishing feature is confidential computing: protecting active data inside an isolated trusted execution environment, rather than limiting protection to stored data or data moving between systems.
TechCrunch attributes to Google the claim that TPU 8tx builds security into the hardware layer to protect and isolate sensitive data and model weights while they are in use. That is the stated security objective; the supplied reporting does not include an independent security evaluation or a detailed account of the protection boundary.
Host interfaces and networking
ServeTheHome reports that Google selected Turin to match TPU 8t’s PCIe Gen5 x16 interface. A dual-socket configuration provides 128 Gen5 lanes, which the report says accommodates four TPUs and high-speed network interface cards without I/O oversubscription. The relevant design choice is the match between the host interface and the accelerator interface, rather than simply choosing a newer host generation.
The same account says Google explained that a Gen6 host such as AMD EPYC Venice would step down to Gen5 speeds without adding accelerator bandwidth. That explanation is specific to the reported configuration. It does not establish a general comparison between the host processors for other workloads.
TPU 8tx also changes the accelerator network. ServeTheHome says it adopts the Boardfly topology used by inference-oriented TPU 8i instead of TPU 8t’s training-oriented torus. The report describes a maximum network-hop diameter of seven for Boardfly, compared with sixteen for the torus design. In practical terms, those figures describe the maximum number of network hops between chips in the respective designs.
This matters to the intended combination of training and reasoning. TechCrunch reports that a custom inference network allows TPU 8tx to run reasoning alongside training, supporting the distillation and training of smaller models on the fly. Google presents training on proprietary data without moving that data between devices as a possible use case.
ServeTheHome attributes to Google a claim of up to 2x lower latency than TPU 8t, alongside a near-zero performance penalty. The supplied account does not give the workload, measurement conditions or baseline for the penalty statement. These are vendor claims with incomplete test context, not independently verified results that can be applied to every training or inference job.
TPU 8i Max and the memory-capacity discrepancy
TPU 8i Max takes a packaging approach: two low-latency TPU 8i chips combined into one multi-chip package. ServeTheHome reports double the compute, double the on-chip SRAM and double the high-bandwidth memory bandwidth of a single TPU 8i. Its reported specifications include 384 GB of high-bandwidth memory, 17.2 TB/s of HBM bandwidth and 768 MB of on-chip SRAM.
The following comparison captures the reported differences without treating the products as interchangeable:
| Attribute | TPU 8tx | TPU 8i Max |
|---|---|---|
| Foundation | TPU 8t silicon with custom AMD EPYC Turin hosts | Two TPU 8i chips in one package |
| Main reported purpose | Confidential training and inference | Inference with large context windows |
| Network detail | Boardfly replaces TPU 8t’s torus | Built from inference-focused TPU 8i chips |
| Quantified claim | Google claims up to 2x lower latency than TPU 8t | ServeTheHome reports 17.2 TB/s HBM bandwidth and 768 MB SRAM |
| Key qualification | Security and performance claims lack independent validation in the supplied reporting | Reports conflict on the relative memory-capacity increase |
TechCrunch describes TPU 8i Max as doubling memory capacity, processing power and bandwidth. ServeTheHome instead gives its 384 GB memory capacity as about a third more than TPU 8i, while agreeing that bandwidth doubles. Those statements cannot both describe the same capacity increase against the same baseline. The supplied material does not explain the discrepancy or document different comparison configurations, so the capacity multiplier remains unresolved.
Memory capacity and memory bandwidth should therefore remain separate in any reading of the announcement. The reporting agrees on a bandwidth increase, but that agreement does not settle how much more information the package can hold relative to TPU 8i. Nor does a reported doubling of compute or bandwidth establish a doubling of application performance.
Market context and competitive landscape
TechCrunch places the launch within a broader effort by technology companies to develop AI-specific semiconductors and accompanying software, citing Microsoft, Amazon, OpenAI and Anthropic. Its account describes reducing reliance on Nvidia as a motivation for that activity, and reducing dependence on other chip suppliers as part of Google’s cloud strategy.
The new TPU configurations fit that direction by expanding the workloads Google’s existing accelerator family is intended to handle. Confidential model execution and larger-context inference create different reasons to consider that family. In editorial terms, broader workload coverage could make an internal hardware portfolio more useful; it is not evidence that customers have already shifted workloads or that Google has reduced external purchases by a measurable amount.
The supplied sources contain no comparable Nvidia benchmark, competitor pricing or deployment figures. They therefore support an account of Google’s positioning, rather than a ranking of its hardware against rival platforms. An assessment of cost, energy efficiency or throughput leadership would require evidence absent from this package.
AMD’s role adds another dimension. TPU 8tx pairs Google’s accelerator with AMD host processors, showing that an internally developed accelerator strategy can still depend on external technology elsewhere in the system. Here, the reported host choice is tied to interface matching and confidential computing, not simply to sourcing an alternative accelerator.
ServeTheHome interprets the arrangement as a meaningful win for AMD because EPYC secures a role in a non-AMD accelerator system at a major hyperscaler. That is a useful description of the design win’s significance, but it does not establish a resulting server market-share change. No purchase volumes or financial terms are supplied.
The same report says this is the first time Google has introduced four distinct TPU system configurations in one year, while emphasizing that these are not four new chip designs. That distinction helps explain the competitive approach: specialization can come from how existing components are assembled and connected, as well as from a new accelerator design. TPU 8tx’s host and network choices and TPU 8i Max’s combined package illustrate those different routes.
Implications for AI workloads and confidential computing
For organizations considering these systems, the first question is which requirement controls the deployment. The reports position TPU 8tx for regulated enterprises and governments running frontier or proprietary models alongside sensitive data. TPU 8i Max addresses the memory demands associated with large-context inference. Neither description makes one a universal replacement for the other.
ServeTheHome says Google advised keeping inference and serving on TPU 8tx when data must remain within the confidential computing domain. That guidance is consequential: a workload’s security requirement may determine the appropriate system before the larger package’s memory resources enter the decision. The supplied evidence does not establish equivalent confidential-computing functionality for TPU 8i Max.
For TPU 8tx, the potential value extends across training and execution. Google’s reported example of training smaller models on proprietary data without moving it between devices connects the security objective to the combined training-and-reasoning capability. It remains a vendor-described use case, rather than a documented customer deployment with measured operational results.
For agentic workloads, ServeTheHome connects Boardfly’s shorter network paths to systems making many sequential inference calls. That provides a plausible architectural reason to care about interconnect latency: the network is part of how the system supports repeated reasoning steps. Still, the topology figures alone cannot predict the latency of a complete agent workflow, and the supplied reporting includes no end-to-end agent benchmark.
TPU 8i Max addresses a different constraint. ServeTheHome describes agents working across an entire codebase or hours of video as examples of workloads where memory bandwidth can become a bottleneck before compute. Those are reported workload motivations, not evidence of a particular deployed service or a measured result on the new package.
The practical distinction is between holding more information and moving information faster. The reported 384 GB capacity describes available HBM; the reported 17.2 TB/s describes bandwidth. Both are relevant to the large-context positioning, but the unresolved capacity comparison limits how confidently buyers can quantify the improvement over TPU 8i. The evidence also supplies no supported context-window size for a particular model.
Evaluation would therefore need to close several concrete gaps: confirm the applicable memory configuration, establish performance on the intended workload, and understand the security boundary for confidential execution. Pricing, availability and application-level measurements would also be necessary for a procurement decision. Their absence does not negate the architectural changes, but it limits the conclusions that can be drawn from the launch.
What the announcement establishes is a more differentiated TPU portfolio. TPU 8tx combines confidential execution with a network adapted for inference, while TPU 8i Max concentrates two inference chips and larger memory resources into one package. The meaningful choice depends on the workload’s protection and memory requirements; the supplied evidence does not yet quantify the resulting operational advantage.