Introduction to Norton Revamp and its purpose
Gen Digital’s Norton Revamp uses an AI-curated News Engine to connect professional reputation management with current web information. The platform, which launched in March 2026 according to the company’s account, combines personalized news discovery, content suggestions and professional goal setting. Its central proposition is that useful professional content requires awareness of developments in a user’s field, alongside the ability to generate text.
The News Engine uses Web Search on Amazon Bedrock AgentCore to retrieve information that can ground those recommendations. A professional pursuing a reputation in generative AI, for example, receives material tied to AI developments and industry analysis. The platform then connects that discovery process to content coaching and a roadmap for professional activity.
The implementation is described in an AWS case study coauthored by Gen Digital and AWS personnel. That is the source for the product details and performance figures discussed here. It provides an engineering account of the system, rather than an independent assessment of whether using Norton Revamp improves a person’s professional reputation.
The distinction matters because the case study describes several different outcomes: current information retrieval, personalized content generation and faster software development. Those capabilities support the product’s purpose, but they do not establish that generated posts produce better professional opportunities. The more concrete finding is how Gen connects web retrieval, ranking and generation within a goal-driven workflow.
Overview of the AI-curated News Engine
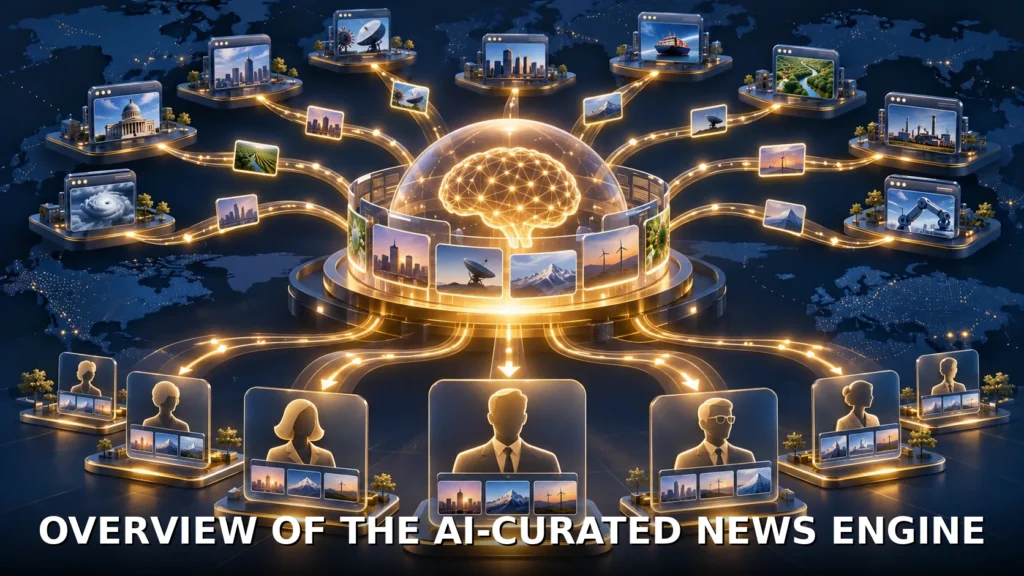
The News Engine supports three connected features. First, a personalized feed surfaces articles and topics relevant to a user’s professional goal, refreshing with each session. Second, content suggestions turn current developments into ideas for posts, with optional AI-generated visuals. Third, trend-aware goal setting produces a roadmap with weekly themes and milestones. The company says recommendations incorporate the previous four weeks of activity.
Content coaching follows an Analyze, Refine, Post flow that takes users from an initial idea toward publication on LinkedIn and X. Gen describes suggestions as tailored to the user’s voice and says a feedback loop adjusts the system over successive interactions. The account does not provide an independent measure of how accurately that voice is reproduced.
The underlying architecture separates discovery from generation. When users set or update a professional goal, Amazon Nova through Amazon Bedrock generates targeted search queries using the goal, recent activity and engagement patterns. An agent sends those queries to AgentCore Web Search, which returns snippets, source URLs, titles and publication dates.
Gen’s AI Learning System then ranks the results for relevance, recency and source credibility. The ranked material becomes grounding context for Amazon Nova Lite to generate content suggestions. Engagement data feeds back into query generation, connecting subsequent searches to earlier user activity. The analytical significance is that personalization influences both what the system searches for and what it writes from the results.
The platform also has distinct processing stages. A Full Scan can retrieve up to 1,000 historical posts, store them in Amazon S3 and use Amazon Bedrock batch analysis to assess reputation impact. A Daily Scan performs incremental analysis triggered by Amazon EventBridge. Weekly Goal Generation combines engagement history with current trend information, while Content Coaching uses synchronous Amazon Bedrock calls grounded in search results.
These stages give the product historical and current context. Historical activity informs the assessment of a user’s existing presence; web retrieval supplies information about developments beyond that history. The case study explains how those inputs enter the workflow, although it does not publish the prompts or ranking formula needed to reproduce the resulting recommendations.
Benefits of using AgentCore Web Search
Gen says it evaluated custom crawlers, third-party news APIs and static knowledge bases before choosing AgentCore Web Search. Its account identifies different problems with each approach: crawlers required maintenance and lagged current developments; news APIs introduced vendor contracts, API key management and data leaving the AWS environment; static knowledge bases became stale.
AgentCore Web Search is described as a fully managed search capability available through a managed connector on AgentCore Gateway. It supports the Model Context Protocol, or MCP, which provides the interface used by the integration. The agent submits a natural-language query and receives search material with source information for grounding its response.
For this application, the combination of retrieval and source metadata is central. A snippet can provide relevant context, while its URL and publication date help the application assess origin and freshness. Gen’s architecture uses those results as inputs to its own ranking and generation stages. The managed connector therefore supplies a retrieval capability within a broader editorial and personalization process.
The authors say the service removed the need to operate their own retrieval infrastructure and kept the search integration within AWS, with zero data egress. Those are vendor-reported descriptions of this deployment. The supplied account does not include an independent data-flow audit, comparative operating costs or latency measurements that would establish the same advantages for every prospective implementation.
Freshness also involves a deliberate compromise. Although the feed refreshes with each session, Gen recommends caching queries that do not need to run every time. It sets time-to-live values according to freshness requirements. A refreshed experience consequently should not be interpreted as a guarantee that every underlying search is newly executed for every visit.
The team also emphasizes structured query generation and engagement feedback. Its reported experience suggests that adopting managed retrieval leaves substantial application work: deciding what to ask, how long results remain useful and which user signals should change future queries. Gen reports that relevance improved over the first 90 days, but supplies no numerical relevance score or evaluation method for that improvement.
Development process and team structure
Gen says a small group of engineers built the platform and moved from concept to production in months. The account does not specify the team’s headcount or a precise development duration. It describes generative AI as both a product capability and a development aid, with different responsibilities assigned to people and tools.
Humans owned architecture decisions, security reviews, business logic and personalization algorithms. AI assisted with code generation, documentation, test scaffolding, refactoring and UI components. The authors also describe AI assistance with security implementation, batch processing optimization and the DynamoDB architecture, while stressing that experienced judgment remained necessary.
The distinction between ownership and assistance is important. Generating an implementation did not transfer responsibility for how the learning system should adapt to user goals. In Gen’s account, engineers designed that behavior and reviewed the output used to build it.
The company reports generating 10 or more design variants per concept with Claude, reducing design-to-prototype time from weeks to hours and producing 70 percent of UI code with AI. It says the team tested five pricing models in the time previously required for one, and that the gamification system went through eight iterations before launch. These figures describe the team’s reported development experience; the account does not provide the baselines or measurement procedure needed for an independent productivity comparison.
Reported gains also carried a review cost. Gen says feature implementation was three times faster, while reviewing AI output consumed 20–30 percent of the team’s time. Those figures should be considered together. The case study presents faster production alongside a substantial continuing need to inspect and judge generated work.
The software used an established application stack: React, TypeScript and Tailwind CSS on the frontend, with Node.js and AWS services on the backend. Infrastructure was managed through Terraform with blue-green deployment. Managed web search was one part of that system, alongside storage, processing, monitoring and deployment components.
Gen reports 85 percent code coverage through automated test generation. Its testing included content quality, search relevance and freshness, engagement tracking, gamification and alignment between feeds and user goals. Security checks covered static analysis, dependencies, authentication, encryption, access controls, model output validation and content filtering. The company also reports 99.9 percent uptime since launch, without specifying the measurement window beyond that description. Coverage and uptime provide useful operational context, but neither directly measures the factual quality of generated posts.
Importance of credibility in content curation
The News Engine’s credibility scoring layer addresses a problem that freshness alone cannot solve: a recent result still needs assessment before it becomes the basis for professional content. Gen says it built a lightweight layer to prioritize authoritative sources, using search results that include URLs and publication dates.
In the documented architecture, credibility is considered alongside relevance and recency before results become grounding context. That placement makes source selection part of generation, rather than merely adding references after text has been produced. For a product intended to support professional reputation, the choice of material shaping a recommendation is a consequential design decision.
However, the case study does not disclose the credibility formula, its weighting against other ranking signals or the criteria used to designate a source authoritative. It also provides no benchmark showing how often the layer rejects unreliable material. The evidence supports describing an implemented prioritization mechanism, without treating that mechanism as a demonstrated guarantee of accuracy.
The same qualification applies to citations. Source URLs make the underlying material identifiable, but the account does not report a measured rate of factual errors or unsupported statements in generated content. Grounding gives the model material to work from; evaluating whether its final suggestion faithfully reflects that material remains a separate question.
Gen’s testing and monitoring approach acknowledges several parts of this problem. The team says it validates search freshness and relevance, tests generation quality and monitors generative AI content quality and user satisfaction. It also describes model output validation and content filtering among its security checks. These are documented areas of attention, although the supplied evidence gives no detailed evaluation results for them.
The practical implication is that credibility cannot be assessed from the presence of web search alone. In this implementation, search, ranking, generation and review all contribute to the result. The published description makes those responsibilities visible while leaving their effectiveness only partly quantified.
Conclusion on the role of generative AI in engineering
Norton Revamp illustrates two uses of generative AI operating together. Within the product, models use retrieved information and engagement history to produce personalized suggestions and goals. During development, AI helped engineers generate and revise software, documentation and tests. Gen explicitly distinguishes those roles in its account.
The reported results support a qualified conclusion: this team used AI assistance and managed services to accelerate delivery while retaining human ownership of consequential design and security decisions. The time spent reviewing AI output is part of that result, as are the claimed implementation gains. Neither can be excluded from an assessment of the development approach.
The News Engine’s clearest contribution is the connection between a professional goal, current source material and content coaching. Its value as an engineering example lies in that integration and in the explicit attention to query quality, caching, feedback and source credibility. Whether those mechanisms improve professional reputation, and how reliably they produce accurate content, remain questions the supplied case study does not resolve.