
Introduction to Amazon SageMaker HyperPod
Amazon SageMaker HyperPod Data Capture records live inference inputs and outputs in Amazon S3, giving teams a record of how deployed models respond to actual requests. Its practical value is the connection it creates between serving a model and finding material for its next training cycle. Capturing traffic can expose questions and failure patterns that a dataset assembled before deployment never contained.
In its Data Capture walkthrough, AWS illustrates that connection with a home-appliance support-ticket router. A new product creates a classification gap; captured requests supply evidence of that gap; and the proposed workflow takes those records through analysis, labeling, fine-tuning, and redeployment. The example uses synthetic traffic, so it should be read as a demonstration of the workflow rather than evidence of results from a retailer’s production system.
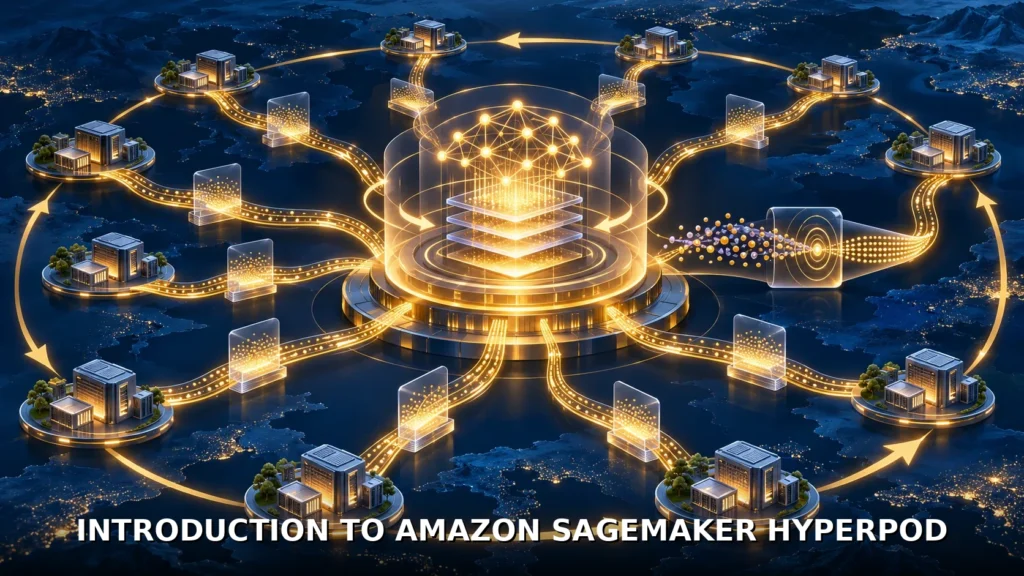
The supplied source describes a single HyperPod cluster orchestrated by Amazon Elastic Kubernetes Service, with an inference operator serving the model and a training operator handling fine-tuning on another node. This arrangement puts inference and training within the same cluster, while assigning each its own GPU resources.
AWS describes the capture capability as having minimal latency impact and zero impact on model availability. Those are vendor claims: the supplied evidence contains no latency measurements or availability study with which to assess them independently. The stronger supported conclusion is architectural: Data Capture provides a way to retain inference evidence and make it available to an improvement workflow. Whether that workflow improves accuracy depends on the analysis, labels, training, and evaluation that follow.
Overview of Data Capture feature
Data Capture offers three independently selectable tiers positioned at different points in the request path: the SageMaker endpoint, the load balancer, and the model pod. Teams can enable combinations within the same dataCapture block. The choice determines whether they collect payloads, traffic metadata, or both.
The walkthrough uses model-pod capture, identified as Tier 3. Its enabling setting is dataCapture.modelPod.enabled: true. This tier records request and response payloads along with event metadata, then writes the records to S3. Configuration options cover sampling, buffering, maximum payload size, encryption, and content types.
For the demonstration, AWS sets sampling to 100%, a batch size of 50, a flush interval of 60 seconds, and a maximum payload size of 1024 KB. These are example settings, not all defaults. The source lists the default batch size as 10 and the default flush interval as 60 seconds; it also says that the default payload size has no limit. Its optional configuration describes payloads exceeding a configured maximum as truncated. That matters for downstream analysis: a stored record may not contain the complete original payload when that limit applies.
Captures arrive as .jsonl objects, with each line representing one inference. The record contains captureData.endpointInput, captureData.endpointOutput, and eventMetadata, including an event identifier and inference timestamp. In the supplied example, the request and response bodies are base64-encoded. An analysis process must decode those fields and then parse the JSON bodies to inspect what the client submitted and what the model returned.
Collection also depends on the request path. In the walkthrough, the capture proxy listens on port 8081 and the model listens on port 8000. Requests sent directly to the model port bypass capture. Consequently, a healthy endpoint and successful model responses do not by themselves establish that inference records are being collected. Verification needs to include records reaching the expected S3 location after the buffer flushes.
Importance of recording inference data
The router example explains why preserving inputs and outputs together matters. The model classifies appliance-support tickets into six categories: ProductFridge, ProductWasher, ProductOven, ProductDishwasher, ProductMicrowave, and Other. It uses vLLM guided JSON decoding to constrain responses to a valid object containing one of those labels.
The synthetic retailer then introduces an air-conditioner line called Arctis. The deployed router has no dedicated air-conditioner category. Its output constraint can keep the response structurally valid, but it cannot create the missing category. A valid response therefore does not establish that the routing scheme adequately represents the incoming request.
Capturing both sides of the exchange preserves the evidence needed to investigate that mismatch: the customer’s product reference, the available classification instructions, and the model’s chosen response. Traffic counts or error codes alone would not explain the same semantic problem. For this use case, the payload is the evidence that connects a new kind of customer request to an inadequate label set.
AWS’s synthetic production dataset contains 900 tickets replayed over 15 minutes. The first 400 contain no air-conditioner requests. Among the remaining 500, the share of Arctis tickets rises from 15% to 55%. That design creates an explicit change in the traffic presented to the model. It is a controlled demonstration of a changing input mix, not a measured rate of change in an operating business.
The example also defines a separate evaluation set of 280 labeled tickets, with 40 for each of seven categories, including the new ProductAC label. AWS says this set is held out by content: its symptoms, sentence templates, and Arctis model names do not appear in the replayed traffic. That separation is relevant because an improvement workflow needs a way to assess behavior beyond the exact records used for training.
The editorial implication is straightforward: recording inference data can make a coverage gap inspectable, but recording does not diagnose or repair it automatically. The router’s missing category requires a decision about the intended output taxonomy as well as work on the model. The supplied example supports that distinction more clearly than a general claim that logging alone improves accuracy.
Three-tier architecture of Data Capture
The three capture tiers serve different purposes. AWS’s description makes the payload-versus-metadata distinction central to choosing among them.
| Tier | Capture point and contents | Uses identified by AWS |
|---|---|---|
| Tier 1 | SageMaker endpoint; full request and response payloads | Compliance, Model Monitor, and audit |
| Tier 2 | Load balancer; ALB access-log fields such as request line, status codes, timings, client IP, and user agent | Traffic and error-rate monitoring |
| Tier 3 | Model pod; full request and response payloads plus event metadata | Debugging, analytics, and training-data collection |
Tier 1 uses SageMaker native data capture. Tier 2 uses Application Load Balancer access logs. Tier 3 is managed by the HyperPod inference operator through NGINX, an OpenTelemetry collector, and an S3 uploader. AWS cautions that Tiers 1 and 3 both store full payloads, creating duplicate storage when both capture the same records. The tiers should therefore be selected according to the evidence required, rather than enabled indiscriminately.
For Tier 3, the inference operator adds three sidecars to the model pod: sidecar-reverse-proxy, otel-collector, and s3-uploader. Together with the model container, that produces four containers in a capture-enabled pod. Requests passing through NGINX are copied to the OpenTelemetry collector, batched, and written to S3 through a Mountpoint-S3 volume. Athena reads the resulting files in place.
The storage path introduces an operational dependency that is easy to miss. According to AWS, the Mountpoint-S3 CSI driver authenticates with its own IAM role for service accounts, rather than the model pod’s service account. Its permissions must include the documented S3 write operations and, when kmsKeyId is configured, the relevant AWS KMS permissions. The inference operator execution role needs its own permissions as well.
AWS explicitly describes a failure mode in which missing driver permissions leave the endpoint healthy and requests successful, while no capture files appear. That makes S3 delivery a separate operational check from model readiness. The training pod’s service account also needs access to the base model and training data, plus permission to write the merged model; Athena requires access to the capture prefix and a query-results location.
Full payloads also carry a data-handling obligation. The source warns that Tier 3 records may contain names, addresses, and order numbers. AWS recommends sampling, AWS KMS encryption through kmsKeyId, S3 lifecycle rules, and personally identifiable information redaction, for example with Amazon Comprehend. These are recommended protections; the supplied evidence does not establish automatic redaction as part of enabling capture. Captured interactions need protection before reuse as training data.
Implications for model training and improvement
AWS organizes the example into five stages: capture requests and responses to S3, analyze the records with Athena, label them through a SQL policy, fine-tune on a second GPU using the training operator, and redeploy alongside the original endpoint with capture still enabled. This gives the improvement process a concrete sequence, with captured behavior supplying the material for subsequent decisions.
The resource requirements are part of that sequence. The walkthrough requires an EKS-orchestrated HyperPod cluster with both operators installed, kubectl configured for the cluster, an S3 bucket in the same Region, and two available NVIDIA GPUs. AWS uses an ml.g6e.8xlarge for serving and an ml.g6e.xlarge for training, each with one 48 GB NVIDIA L40S. Because the serving pod retains its GPU for the endpoint’s lifetime, AWS says a training pod remains Pending if only one GPU is available.
The example uses Qwen2.5-3B-Instruct as the base model and describes fine-tuning through a HyperPodPyTorchJob. The revised model is intended to be served by a second endpoint with capture enabled. Continuing collection after redeployment preserves the same route from observed behavior back to analysis; it does not establish that the revised model has solved every failure mode.
There is a material limit to what can be concluded from the supplied evidence. Although the source’s introduction promises before-and-after accuracy measurement, the available text ends as the Athena analysis section begins. It does not include the analysis queries, SQL labeling policy, completed fine-tuning procedure, or measured evaluation results. No numerical accuracy gain, category-level improvement, or training outcome can therefore be reported from this package.
What the evidence does establish is the infrastructure and scenario for a feedback loop: a constrained router encounters a product outside its original category scheme, payload capture preserves those interactions, and a separate evaluation set is defined to assess a revised model. The unresolved question is how successfully the later stages convert that evidence into better behavior. Data Capture supplies an observable starting point; the quality of the resulting model remains something to measure.